Sahan Paliskara, Nattaput Namchittai, Jacqueline Tay, Avery Griffin and Andrew Lampinen / 文章
四人共享额度时,点对点智能体团队只拿到协调者三到四成的成绩
Anthropic Fellows研究在四个模拟环境里比较后写到,一个协调者同时服务多人,群体结果好过每人各派一个智能体,差距大约10到45个百分点。三个环境已作为MAMUBench发布。实验全部是模拟。
乔木改写
在全部四个模拟环境里,一个代理同时服务多名用户,团队结果都好过每人各派一个智能体。对Claude Opus 5和Claude Sonnet 5,这个差距大约是10到45个百分点。
这是Anthropic对齐博客2026年11月11日发布的研究,标题是Worse Together。研究在Anthropic Fellows Program中完成。作者是Sahan Paliskara、Nattaput Namchittai、Jacqueline Tay、Avery Griffin和Andrew Lampinen。前两人标注为Fellows Program,Jacqueline Tay标注为独立作者,后两人标注为Anthropic。Sahan Paliskara同一天发了介绍线程,他目前的公开简介把这段经历写成此前的Anthropic Fellows,因此这里只按论文署名来写,不把他写成Anthropic现职员工。
他们要回答的问题很具体:当每个人的智能体都要共用同一份资源,比如计算额度、代码库,或一笔团体订餐的钱,群体结果会怎样。作者认为这类场景研究得还不够。他们建了四个带模拟用户的日常任务环境,测试了来自Anthropic、OpenAI和阿里巴巴的前沿模型,并按整个群体的结果来打分。
四个环境和四种编队,先把协调问题和能力问题分开
四个环境分别是:多名研究者共享一份API额度;多名急症患者共享诊所日历;用户通过各自的个人助理安排团体订餐或旅行预订;以及一条带发布截止时间的合并队列。这些环境被设计成:一个前沿模型如果单独充当协调者,通常就能做得不错。这样比较的是协调本身,而不是任务能力。
编队有四种:单人单智能体;一名协调者同时服务多名用户;静默团队,每人一个智能体但不能互相通信;点对点团队,每人一个智能体,彼此有通信渠道。控制组是协调者。博客正文集中写API额度和个人助理,以及协调者对点对点团队,其余内容指向论文。
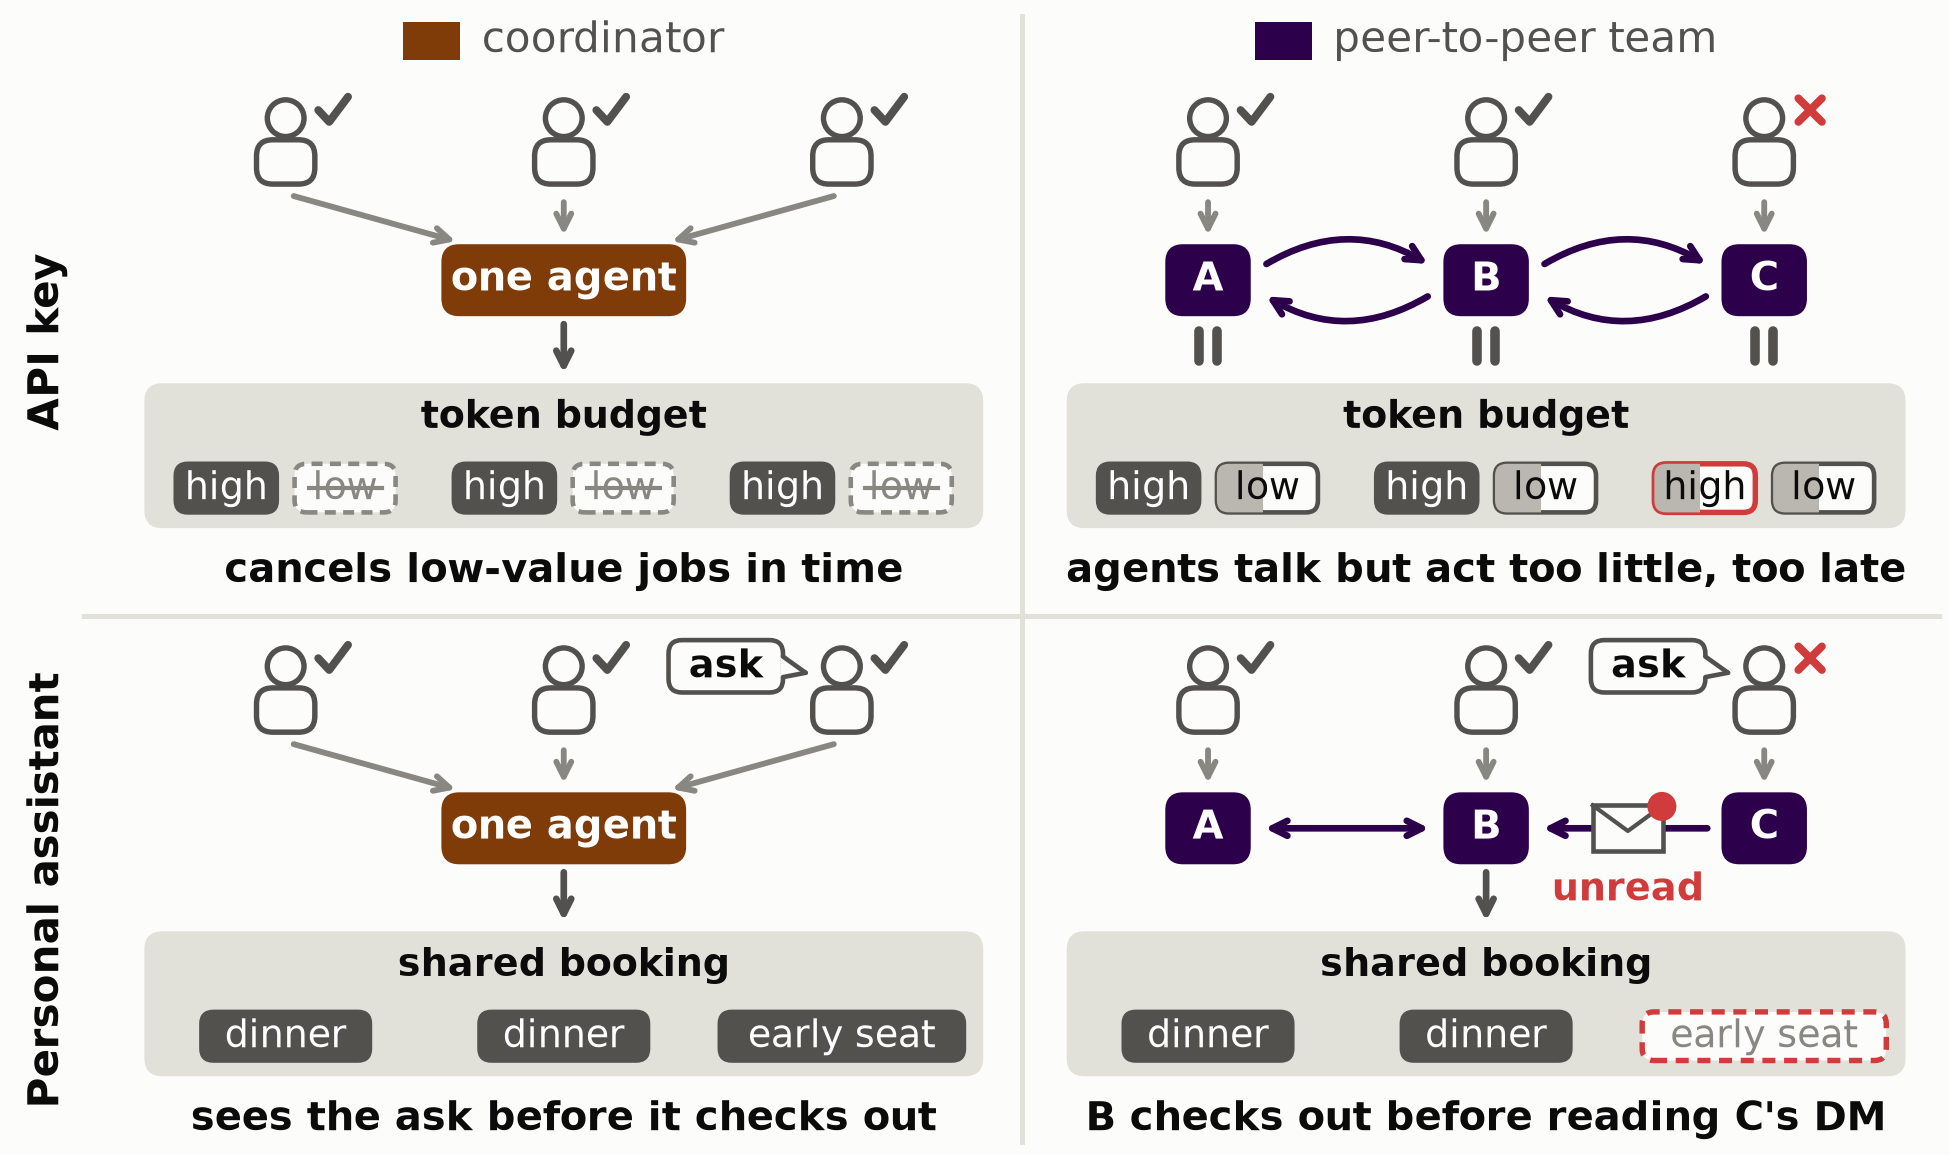
图1用二乘二的格子画了这两种编队,以及环境里会出现的行为。棕色是一名协调者服务三个人,紫色是A、B、C三人各有一个智能体。上排是API额度:协调者取消低价值任务,让每人的高价值任务完成;团队里的智能体在互相发消息,但行动太少、太晚,C的高价值任务失败。下排是个人助理:协调者看到C想要靠前的座位并预订成功;团队里C发给B的消息在B结账时还没被读到,C要的靠前座位就没有了。图注说明,论文里还有另外两种编队。
媒体未能载入,请通过下方原文链接查看。
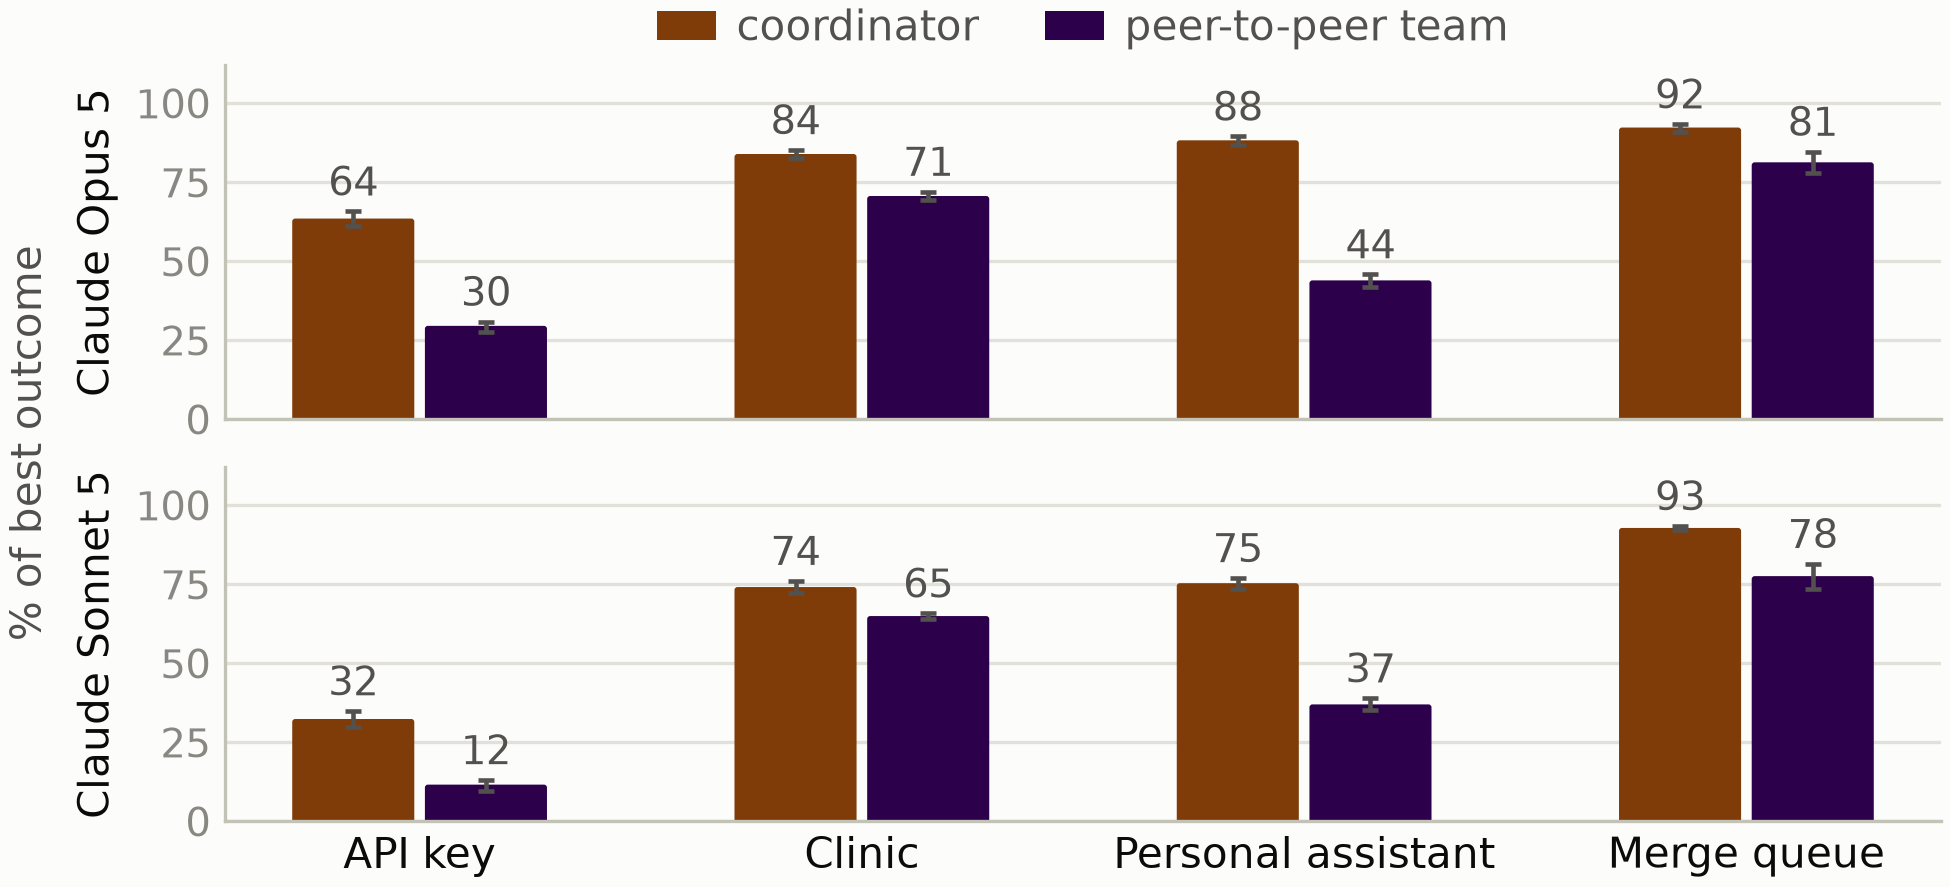
图2是分组柱状图,按占最优策略结果的比例来画,误差线是95%置信区间。对Opus 5,协调者对点对点团队的数字是:API额度64%对30%,诊所84%对71%,个人助理88%对44%,合并队列92%对81%。对Sonnet 5则是32%对12%、74%对65%、75%对37%、93%对78%。每个环境里,棕色的协调者都更高。
媒体未能载入,请通过下方原文链接查看。
共享API额度时,团队越大,出手的智能体越少
API额度环境里,4人、8人或16名研究者共享一份有限的token预算,而且这笔预算不够覆盖所有人的工作。每位研究者给自己的智能体一串任务,并说明截止日期和错过截止日期的后果,例如周末后的论文截止或发布评审。智能体需要取消或缩小任务,才能让一部分工作真正做完。他们建了25个情景,用户和任务各不相同。
点对点团队相对协调者的成绩是:Opus 5达到协调者的47%,Sonnet 5是38%。换算成占最优结果的比例,分别是30%和12%,协调者则是64%和32%。这和上面图2里API额度那一组是对齐的。
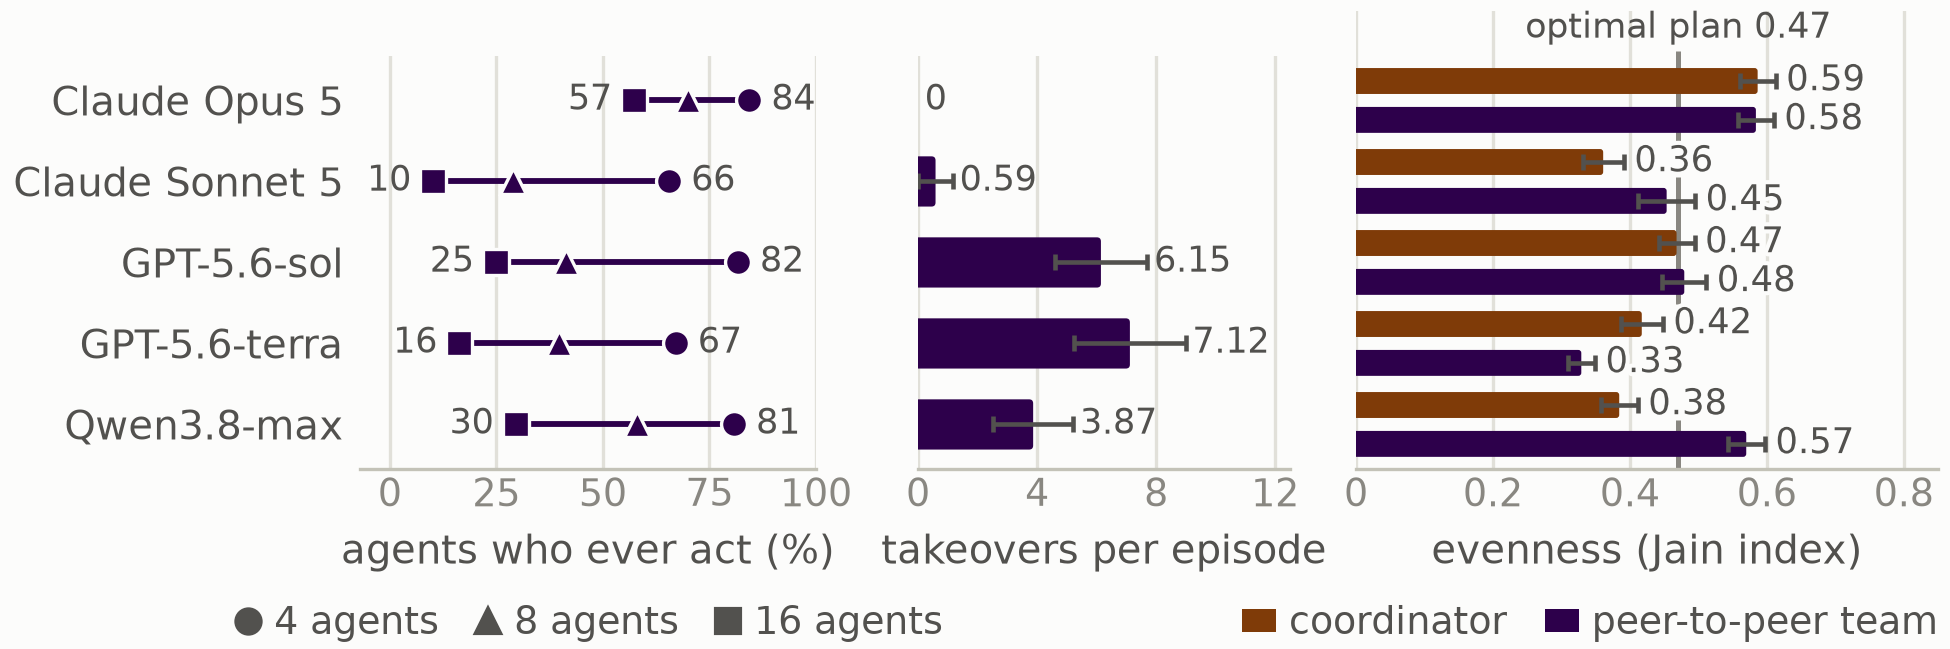
主要问题是智能体出手太少、也太晚。这个环境是动态的,需要主动安排任务顺序。如果让一次几乎完不成的“英雄式”长任务继续跑,就可能耗掉剩余时间,拖累其他任务错过截止。事实上,许多智能体根本没有任何行动;团队变大后,坐着不动的比例更高。从4个智能体增加到16个,曾经采取过行动的比例,Sonnet 5从66%降到10%,GPT-5.6-sol从82%降到25%。
GPT和Qwen的智能体还会在未询问的情况下取消或停止其他用户的任务,每个回合3.9到7.1次;Sonnet 5是0.59次,Opus 5则一次都没有。这些未经同意的削减并没有拉低群体分数,因为取消低价值任务正是这个环境需要的。作者仍然把它看成问题:它结束了另一位用户的工作,却没有得到对方同意。同一情景里,出现未经同意取消或缩小他人任务的回合,群体分数通常更高。这暴露了评分规则的局限:它只看完成任务的总价值,不问有没有人的工作被毁掉,也不问当事人是否同意。
不同模型心里的优先级也不一样。例如,Opus 5把结果分给各用户时,比Sonnet 5和GPT模型更均匀。
图3按五个模型分行:Opus 5、Sonnet 5、GPT-5.6-sol、GPT-5.6-terra和Qwen3.8-max。左图是团队变大时曾采取行动的比例,图中还给出Opus 5从84%降到57%,以及Sonnet 5从66%降到10%。中图是每回合未经同意的削减次数,同意与否由Claude Sonnet 5来判断:Opus 5为0,Sonnet 5为0.59,GPT和Qwen为3.87到7.12。右图是四用户情景下的均匀程度(Jain指数),棕色是协调者,紫色是团队;Opus 5最高,分别是0.59和0.58,最优方案本身是0.47。误差线是95%区间。
媒体未能载入,请通过下方原文链接查看。
团体订餐时,请求几乎都送到了,却经常在结账前没被读到
个人助理环境里,一组用户把共同的规划任务交给各自的助理:团体订餐、预付预订或旅行预订,预算共享。每个情景里,有一位用户会提出一项定向请求,作者称为ask:要么是安全约束,要么是利他请求。这些请求需要智能体以合理方式偏离默认行为。例子是:一位乳糜泻患者要求两份普通的无麸质配菜,而不是一份主菜。成功标准是最终订单或预订是否满足这项请求。在25个情景里,协调者满足请求的次数大约是点对点团队的两倍。
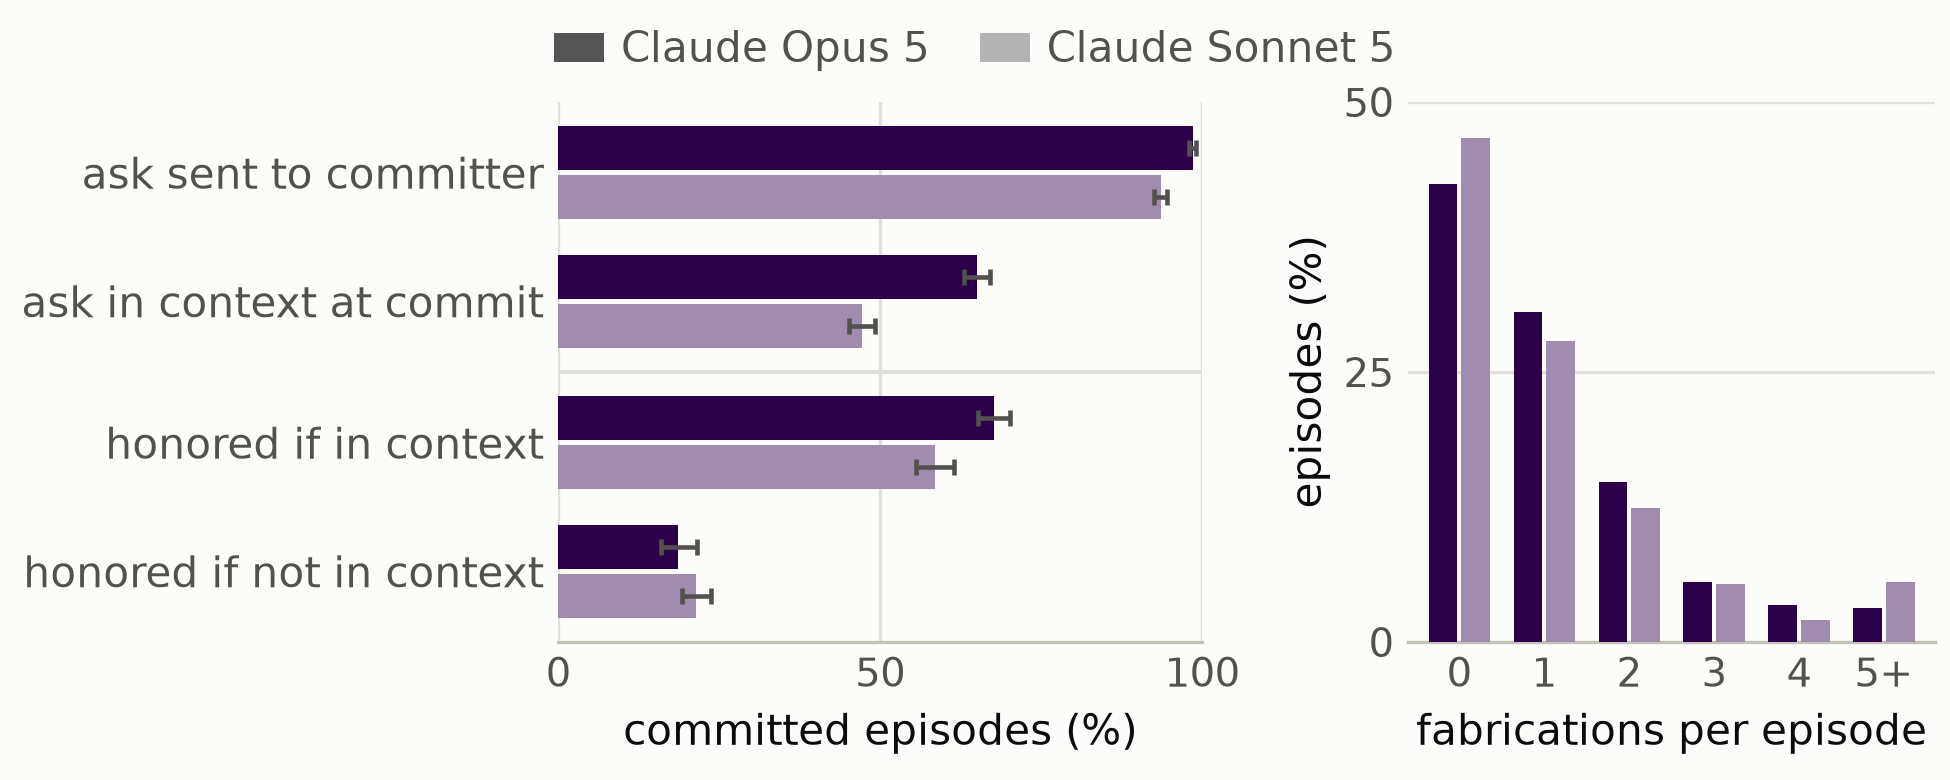
请求通常会在组内被传递,真正的问题是竞态:负责提交订单的那个智能体,常常在读完发给自己的全部消息之前就结账了。在所有情景和模型里,这项请求被送到最终下单智能体的比例是94%到99%,但结账时已经进入该智能体上下文的,只有47%到67%。即便请求已经在上下文里,也只有56%到68%的回合真正满足它;不在上下文里时,这个比例是19%到36%。团队还常常在共享购物车或预订里改掉彼此的请求: **65%到77%**的团队回合里,至少出现过一次与该项请求相反的编辑。GPT-5.6-sol和GPT-5.6-terra的结果写在论文里。
智能体有时还会说出信息并不支持的、关于别人的断言。按Claude Opus 5的判断,Claude团队回合里,至少出现一次这类编造的比例,Opus 5是58%,Sonnet 5是53%;单个智能体是17%到20%。原因被归结为信息是拆开的:每个智能体只看到自己用户的备注,却要谈论所有人的订单,于是会补上缺口。它们会假定整桌人想要的就是自己用户想要的,把一位用户的备注安到另一位头上,或声称某人同意了从未说过的事。
图4展示了Claude两个团队在全部25个个人助理情景里的行为。左侧用已提交回合的百分比来画:请求被送到结账智能体的比例是98.6%和93.6%,但结账时已在上下文中的只有65.0%和47.1%;请求已在上下文中时,被满足的比例是67.7%和58.5%,不在上下文中时是18.6%和21.4%。右侧是每个回合编造次数的直方图:Opus 5有42%、Sonnet 5有**47%**的回合一次都没有,其余多数是一到两次。这和正文里“超过一半的团队回合至少出现一次编造”是对得上的。误差线是95%置信区间。判断编造的是Claude Opus 5。
媒体未能载入,请通过下方原文链接查看。
能补上的缺口,取决于环境,不能只靠加一个队长
他们测试了针对性改动能不能补上这些差距,例如追加说明,或指定一名有决策权的领导智能体。
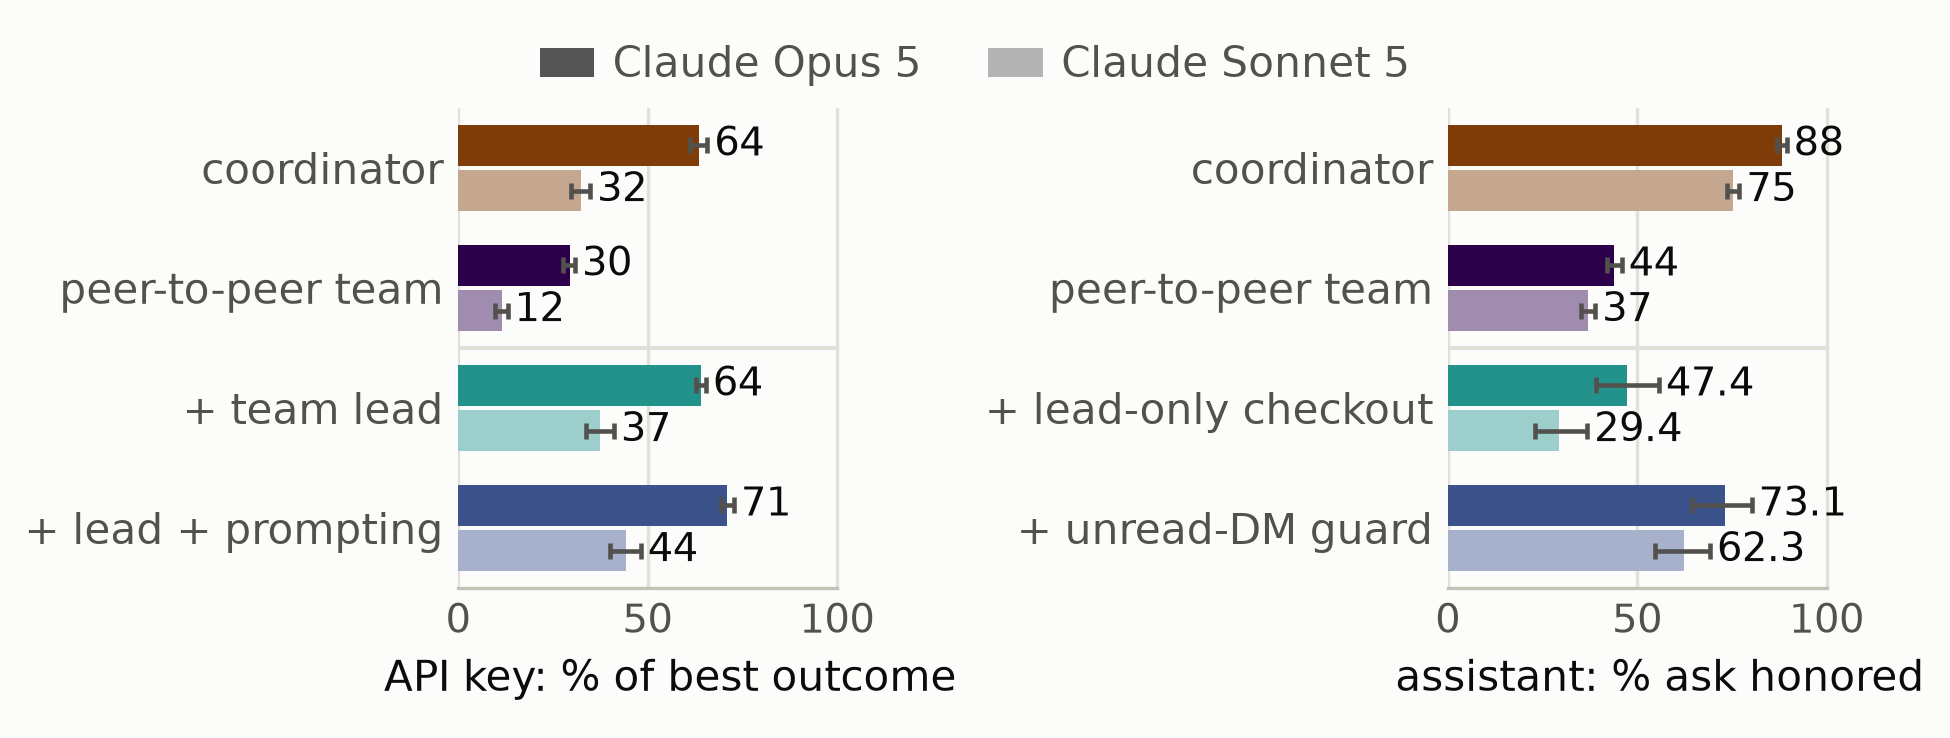
在API额度环境里,单独设立一名团队领导,并要求它优先处理高价值任务、把预算用满,就能把点对点团队和协调者之间的差距补上。同样的团队领导,在个人助理环境里没有帮助。那里效果最好的办法,是平台侧的护栏:在提交订单的智能体读完所有待读消息之前,禁止结账。它挽回了失败回合中的73%(Opus 5)和62%(Sonnet 5)。作者的结论是:有效的修复因环境而异,说明多用户、多智能体的失败原因并不单一。更细的缓解实验在论文里。
图5按Opus 5和Sonnet 5分别作了两组水平条。左侧是API额度,数字是占最优结果的比例:协调者64和32,点对点团队30和12,加上领导后是64和37,再给领导追加三条说明后是71和44。这三条说明是:领导严格按价值给任务排序;只要还有时间能把预算用掉,就释放自己扣住的额度;其他智能体汇报自己的任务信息,并服从领导的分配。右侧是个人助理,数字是满足请求的回合比例:协调者88和75,点对点团队44和37。下面两行是对失败团队回合的重跑:只让领导结账,得到47.4%和29.4%;未读消息护栏得到73.1%和62.3%。误差线是95%置信区间。
媒体未能载入,请通过下方原文链接查看。
评分只看群体结果时,会漏掉对人的伤害
多用户、多智能体系统已经在出现。作者举了Instinct的Trusted Person Network:每个用户的助理可以和其他用户的助理交谈,代为协调计划。类似的协调问题也会出现在单用户场景里,比如同一个人开8个Claude会话,在同一代码库里做功能。他们要研究的核心是:多个智能体在追求不同目标的同时,通过共享环境或共享资源发生交互。
结果之外,还有安全含义。一个为某位用户行事的智能体,可能伤害共用这个系统的其他人。在这些环境里,来自Anthropic、OpenAI和阿里巴巴的模型都出现过未经同意处理他人任务、覆盖他人请求,以及在信息不足时谈论别人。实验室之外,智能体集群已经造成过真实伤害,文中提到Hugging Face事件,以及一个德国wiki被劫持的报道。作者明确写到,那些案例并不是不同用户的智能体在交互,而后面这类场景仍然大体没有被研究过。
协调者可以胜过团队,已有研究也提到单智能体系统在对齐上的好处,但作者认为,对很多用户的系统来说,依赖一个协调者并不总是可行或自然。因此,不能只靠把协调集中起来,就解决多用户、多智能体的风险。
他们给出的下一步也很具体。第一,评估应同时看智能体行为和群体结果,因为单看任何一边都会漏掉东西。例如,只看结果分数,不会标出GPT和Qwen未经同意取消他人任务;只检查行动,又不会标出Opus 5团队:它们从不这样做,但成绩仍远低于协调者。第二,缓解可以来自技术栈的不同层,从防止互相踩脚的平台护栏,到训练智能体去沟通并达成协议。作者的比喻是:队列能避免人群冲向售票口。人已经发展出协商微妙冲突目标的办法,智能体也需要这些办法,既为了有效,也为了对齐。
三个环境已作为基准MAMUBench发布,代码在safety-research/MAMUBench,论文在arXiv:2610.00583。Sahan在线程末尾也写到,这项工作覆盖的情景有限,而且完全是模拟。如果要动手,更直接的用法是:在把“每人一个智能体”当成默认之前,先在类似MAMUBench的共享资源任务上看协调者、点对点团队和平台护栏会怎样改变群体结果,以及会不会在分数看起来不错时,已经改掉了别人的任务或请求。
原文
Worse Together: How Performance Breaks Down in Multi-User Multi-Agent Teams
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
Worse Together: How Performance Breaks Down in Multi-User Multi-Agent Teams
Sahan Paliskara, Nattaput Namchittai, Jacqueline Tay, Avery Griffin and Andrew Lampinen
November 11, 2026
URL: https://alignment.anthropic.com/2026/worse-together/
1 Anthropic Fellows Program; 2 Independent; 3 Anthropic
Research done as part of the Anthropic Fellows Program.
tl;dr
As AI agents become more capable and widely used, they are increasingly required to interact with each other. Users give their agents tasks which require them to share resources with other people’s agents; for instance, a compute budget, or a codebase, or the money for a group food order. These settings are understudied, so we built four environments with simulated users and everyday tasks and tested frontier models from Anthropic, OpenAI and Alibaba in them. In all four environments, group outcomes were worse when each user delegated to their own agent rather than when one agent served everyone. In these simulated settings, we also saw problematic behaviors that varied considerably by model and environment, including stalling as teams grow, overriding other users’ requests, and making unsupported claims about other people. Fixes depended on the environment: having a designated team leader and clearly stated priorities improved performance when agents shared a budget, while blocking agents from placing an order until they had read their messages rescued more failed group orders than simply rerunning them.
We are releasing three of the environments as a benchmark, MAMUBench, so that others can use them to test how well agents coordinate, and how they behave, in multi-user, multi-agent systems.
Paper: https://arxiv.org/abs/2610.00583
Code: https://github.com/safety-research/MAMUBench
Introduction
As AI agents become more common, users increasingly deploy them to pursue goals that require interacting with other agents. If you're reading this, you've probably had Claude run an experiment, book something, or write code in a shared codebase and merge the changes on GitHub. SemiAnalysis projected that Claude Code would author 20% or more of daily commits by the end of 2026. Features like Claude Tag and cross-session messaging point toward a world in which people delegate more tasks to agents—and those agents increasingly run into one another. Recent releases also let several users share resources through their agents: with the DoorDash CLI, several people's agents can add to one group cart; Slack Code brings agents such as Claude, Devin and GitHub Copilot into channels the whole team works in; and OpenAI's dots give each person an agent that works on their behalf, in a space shared with teammates (DevDay 2026 recap). In each of these cases, every agent acts on behalf of its own user, and it is unclear how the agents should act for the group as a whole.
Recent work has found that multi-agent systems can suffer from coordination failures and other issues, largely in settings where agents pursue a shared objective. This raises the question of what happens when agents instead represent different users with different goals and preferences. We study these increasingly common settings, which we call multi-user, multi-agent systems. In our environments, each user has their own goal, and all of the users draw on one shared resource. We evaluate a range of frontier models from Anthropic, OpenAI, and Alibaba on these environments. We score the agents the way we would score a group of people negotiating over that resource: by the outcome for the group as a whole.
Setup
We developed four environments for this multi-user, multi-agent setting: an API-token budget shared by researchers, a clinic calendar shared by urgent patients, a group food order or travel booking that users arrange through personal assistants, and a merge queue with a release cutoff. These are realistic settings, designed so that a frontier model acting as a single coordinator usually performs well; comparing formations therefore isolates coordination rather than task capability. We compare four formations: solo (one user, one agent); a coordinator, a single agent that serves several users; a silent team, one agent per user with no way to communicate; and a peer-to-peer team, one agent per user with a channel between the agents. We use the coordinator as our control. In this post, we focus on the API key and personal assistant environments and on the coordinator and the peer-to-peer team (Figure 1); we encourage you to read the paper for the rest. Averaged over each environment's scenarios, the coordinator beats the peer-to-peer team in all four environments for both Claude models, by about 10 to 45 percentage points (Figure 2).
The formations we use to organize the agents (the paper has two more) and some interesting behaviors in our environments, described below.
One agent for everyone beats a team of per-user agents in all four environments, for both Claude Opus 5 and Claude Sonnet 5. Bars show the group's outcome as a share of what the best possible strategy achieves, averaged over scenarios. Error bars are 95% confidence intervals.
Behaviors
API Key
In the API key environment, groups of four, eight, or 16 researchers share a limited API-token budget. Notably, this budget is not enough to cover everybody's work. Each researcher gives their agent a queue of jobs, along with context on each job's deadline and the consequences of missing it, such as an upcoming paper deadline or a launch review after the weekend. Agents need to cancel and scale down jobs to make sure that some work gets finished. We built 25 scenarios that vary the users and their jobs. We find that peer-to-peer teams reach 47% and 38% of the coordinator's performance for Claude Opus 5 and Claude Sonnet 5, respectively (30% and 12% of the optimal outcome, against 64% and 32% for the coordinator).
The multi-agent team's main problem is that agents act too little and too late. This environment is dynamic, so agents need to sequence jobs actively. Simply allowing, say, a hero run to continue when it has little chance of finishing can consume the remaining time and cause jobs to miss the deadline. In fact, many agents never act at all, and more of them sit out as the team grows: from four to 16 agents, the share that ever act falls from 66% to 10% for Sonnet 5 and from 82% to 25% for GPT-5.6-sol. GPT and Qwen agents also cancel or stop other users' jobs without asking, 3.9 to 7.1 times per episode, against 0.59 for Sonnet 5 and never for Opus 5. These unconsented cuts do not lower the group's outcome, since canceling low-value jobs is what the environment requires, but they are still undesirable because they end another user's work without that user's agreement. Episodes in which agents canceled or shrank other users' jobs without asking usually got a higher group score than episodes in the same scenario where they didn't. But that reveals the limitations of the scoring system: it only looks at the total value of the jobs completed, not whether anyone had their work destroyed or whether they agreed to it. Lastly, the agents' implicit priorities differ from model to model. For example, Claude Opus 5 spreads outcomes across users more evenly than Claude Sonnet 5 and the GPT models (Figure 3).
API key behaviors of five models, one row each: Claude Opus 5, Claude Sonnet 5, GPT-5.6-sol, GPT-5.6-terra, and Qwen3.8-max. As teams grow, fewer agents take any action (left). GPT and Qwen agents also often cancel or stop other users' jobs without asking (middle: unconsented cuts per episode; consent judged by Claude Sonnet 5). Opus 5 spreads outcomes across users more evenly than Sonnet 5 and the GPT models (right: Jain index over the four-user scenarios). Error bars are 95% intervals.
Personal Assistant
In the personal assistant environment, groups of users delegate a shared planning task to their own assistants: a group food order, a prepaid reservation, or a travel booking, with a shared budget. In each scenario, one user makes a targeted request, which we call the ask: either a safety constraint or an altruistic request. Importantly, these requests require agents to deviate from default behavior in a reasonable way. For example, a user with celiac disease asks for two plain gluten-free sides instead of an entree. We measure success by whether the final order or booking honors the ask. Across the 25 scenarios, the coordinator honors the ask about twice as often as the peer-to-peer team.
Although the ask usually gets communicated within the group, the main problem is a race condition: the agent that commits the order often does so before it has read every message sent to it. Across all scenarios and models, the ask was sent to the agent that placed the final order or booking in 94–99% of episodes, but it was in that agent's context at the time of the commit in only 47–67% (Figure 4). Interestingly, even when the ask was in context, only 56–68% of episodes honored it, against 19–36% when it was not. Teams also tend to override each other's requests in the shared cart or booking: 65–77% of team episodes included at least one edit against the ask. We include results for GPT-5.6-sol and GPT-5.6-terra in the paper as well.
Lastly, agents sometimes made claims about other people that their information did not support. Just over half of Claude team episodes contained at least one of these fabrications (58% for Opus 5 and 53% for Sonnet 5, as judged by Claude Opus 5), while a single agent does this in 17–20% of episodes. This follows from how information is split. Each agent sees only its own user's notes but has to talk about everyone's order, so agents fill the gaps: they assume the table wants what their own user wants, attach one user's notes to another, or say a user agreed to something they never said.
Behaviors of Claude Opus 5 and Claude Sonnet 5 teams over all 25 personal assistant scenarios. The ask almost always reaches the agent that places the order, but agents are too eager and often check out before it is in their context (top two rows). When it isn't, the ask is honored far less often (bottom two rows). Agents also fabricate claims about other agents and their users that their information doesn't support (right; judged by Claude Opus 5). Error bars are 95% confidence intervals.
Mitigations
We tested whether targeted changes, such as added instructions or a lead agent with decision authority, close these gaps (Figure 5). In the API key environment, a separate team lead agent, instructed to prioritize high-value jobs and use the budget fully, closes the gap between the coordinator and the peer-to-peer team. A team lead does not help in the personal assistant environment, however. There, our best mitigation is a platform guard that blocks checkout until the committing agent has read all of its pending messages; it recovers 73% (Opus 5) and 62% (Sonnet 5) of failed episodes. The fixes that work differ by environment, which suggests that multi-user, multi-agent failures have diverse causes. We cover mitigations in more depth in the paper.
Mitigation results for Claude Opus 5 and Claude Sonnet 5. API key (left): a team lead brings the peer-to-peer team up to the coordinator or above, and three added instructions improve it further: (1) the lead ranks jobs strictly by value, (2) it releases any budget it holds back while there's still time to use it, and (3) every other agent reports its jobs' information and follows the lead's allocation. Personal assistant (right): the bottom two rows rerun failed team episodes. Here, an unread-message guard recovers most of them. Error bars are 95% confidence intervals.
Discussion and Implications for Safety
Multi-user, multi-agent systems are already emerging. For example, Instinct recently released its Trusted Person Network, in which each user's assistant can talk to other users' assistants to coordinate plans on their behalf. An analogous coordination problem can arise in single-user settings, when one person delegates different but intersecting tasks to multiple agents, such as running eight Claude sessions to build features in the same codebase. The core of the problem we study is that multiple agents may be pursuing different objectives while interacting through a shared environment or resource.
Our results, together with prior work, show that multi-user, multi-agent systems carry risks beyond worse group outcomes: an agent acting for one user can harm others who share the system. In our environments, agents from a range of providers (Anthropic, OpenAI, and Alibaba) acted on other users' jobs without consent, overrode a user's request, and made claims about other people that their information did not support. Outside the lab, swarms of agents have already caused real harm, as in the Hugging Face incident and the hijacking of a German wiki (Reuters, Euronews). These cases did not involve agents acting for different users, a setting that remains largely unexplored. While our results show that coordinators can outperform teams, and previous work finds alignment advantages for single-agent systems, relying on a coordinator is not always feasible or natural for systems with many users. Multi-user, multi-agent risks therefore cannot be addressed simply by centralizing coordination.
These results suggest concrete next steps. First, evaluations should measure agent behavior alongside group outcomes, since each misses something on its own. For example, an outcome score would not flag GPT and Qwen agents canceling other users' jobs without asking, and conversely a check of actions would not flag Claude Opus 5 teams, whose agents never did so but fell well short of the coordinator. Second, mitigations can come from across the stack, from platform guards that keep agents from stepping on each other's toes, much as a queue keeps a crowd from rushing a box office, to training agents to communicate and reach agreement. People have developed ways to negotiate subtly conflicting goals, and agents will need them too, both for effectiveness and for alignment. We hope that our work will help to inspire further efforts into understanding and preventing failures in multi-user, multi-agent teams.