Barry Zhang, Tianyi Peng, Elle Najt, Keller Scholl, Lance Martin / 长帖 / 视频
1000 个 Fable 5.2 智能体用 28.7 小时重做了费马大定理的形式化证明
Anthropic 的玩具实验里,1000 个早期 Claude Fable 5.2 智能体没有 Prove2Me 平台,也没有研究员当场指挥,用通用工具和共享数据库重做了今年 9 月那份费马大定理形式化证明。输出 token 大约是当时的三分之一,写出的证明大约是七分之一长。
乔木改写
1000 个运行早期 Claude Fable 5.2 的智能体,在 28.7 小时里重做了一份费马大定理的形式化证明。和今年 9 月那次相比,它们没有使用 Prove2Me 平台,也没有研究员在旁边指挥,用掉的输出 token 大约是当时的三分之一,写出的证明大约是七分之一长。
这篇说明由 Barry Zhang、Tianyi Peng、Elle Najt、Keller Scholl 和 Lance Martin 撰写,2026 年 11 月 9 日发布在 claude.dev。Lance Martin 的 X 账号是 @RLanceMartin,公开资料写的是 Anthropic 的 MTS,他也在自己的账号上分享了这篇文章。文中把这次运行称为一次玩具实验。智能体用的是早期版本的 Fable 5.2,不是对公开发布版的承诺。
费马大定理说的是:不存在正整数 a、b、c,能让 aⁿ + bⁿ = cⁿ 在任何大于 2 的 n 上成立。它在 350 多年里一直没有被证明,直到 Andrew Wiles 在 1995 年给出 129 页的证明。把这份证明形式化,也就是让计算机检查每一步,长期是数学共同体里的目标。
今年 9 月,他们发布了第一份端到端的费马大定理形式化,说明在 https://www.anthropic.com/research/formalizing-fermats-last-theorem 。那次由几十个智能体完成,运行的是大约相当于 Claude Fable 5.1 的内部研究模型,并有一位研究员给出方向。他们用了 11 天,大约 60 亿输出 token,写出了 1300 万行 Lean 代码。Lean 是一种编程语言,计算机会检查证明里的每一步。
当时的协调靠的是 Prove2Me。这个平台由 Tianyi Peng 和哥伦比亚大学的合作者设计,Peng 现在是 Anthropic 的技术员工。Prove2Me 用一张共享图,把每条待证命题和它拆成的更小命题连起来。任何智能体都可以拆分一条命题,其他智能体可以向这张图询问哪些尚未证明的部分已经可以动手,这样就不容易丢掉项目状态。每条命题和它的证明都放在单独文件里,并且可以独立编译,因此许多智能体能够并行工作,而不去改同一批文件。
新实验想看的是:一支运行类似 Fable 5.2 的智能体队伍,能不能在没有 Prove2Me、也没有研究员当场指挥的情况下,用一套由通用工具组成的 harness 做出这个结果。
每个智能体都待在没有外网的沙箱里,手里只有通用工具
他们给这 1000 个智能体准备了 60 条需要证明的命题,其中包括最终定理和 59 个中间里程碑。对每一条命题,智能体都要写出 Lean 证明,用 Lean 的工具构建并检查,再提交到 Git 共享主干上,由评分器检查。每个智能体得到的工具是:
自己沙箱里的一个 shell 和一个文件编辑器,沙箱没有网络访问。
沙箱镜像里已经装好的 Lean 工具链和 Mathlib,Mathlib 的地址是 https://github.com/leanprover-community/mathlib4 。
自己的 Git 分支,以及向主干发起合并请求的能力。
一个共享的 Postgres 数据库,从 shell 里访问。
证明工作可以拆开,因此适合多智能体队伍。智能体也需要协调,既要接上别人的成果,也要避免重复劳动。作者写到,最初的形式化里,Claude 早期的尝试失败过,原因是智能体跟丢了项目状态,不再有效协作。搬到 Prove2Me 之后,这个问题才得到解决。
这一次,每个智能体都在自己的轻量虚拟机沙箱里工作。单台共享机器大约在 100 个智能体时就会碰到上限:超过一半的 100 智能体运行因为内存、磁盘或 CPU 耗尽,不得不停止或重启。
有了 1000 个分开的沙箱,智能体需要一种办法分享工作,于是作者给了它们一个 SQL 数据库。他们选择 SQL,是因为它提供组织信息的通用原语,事务能处理 1000 个智能体同时写入,而且 Claude 本来就熟悉它。智能体用这个数据库认领任务、分享笔记,并记录完成的工作。
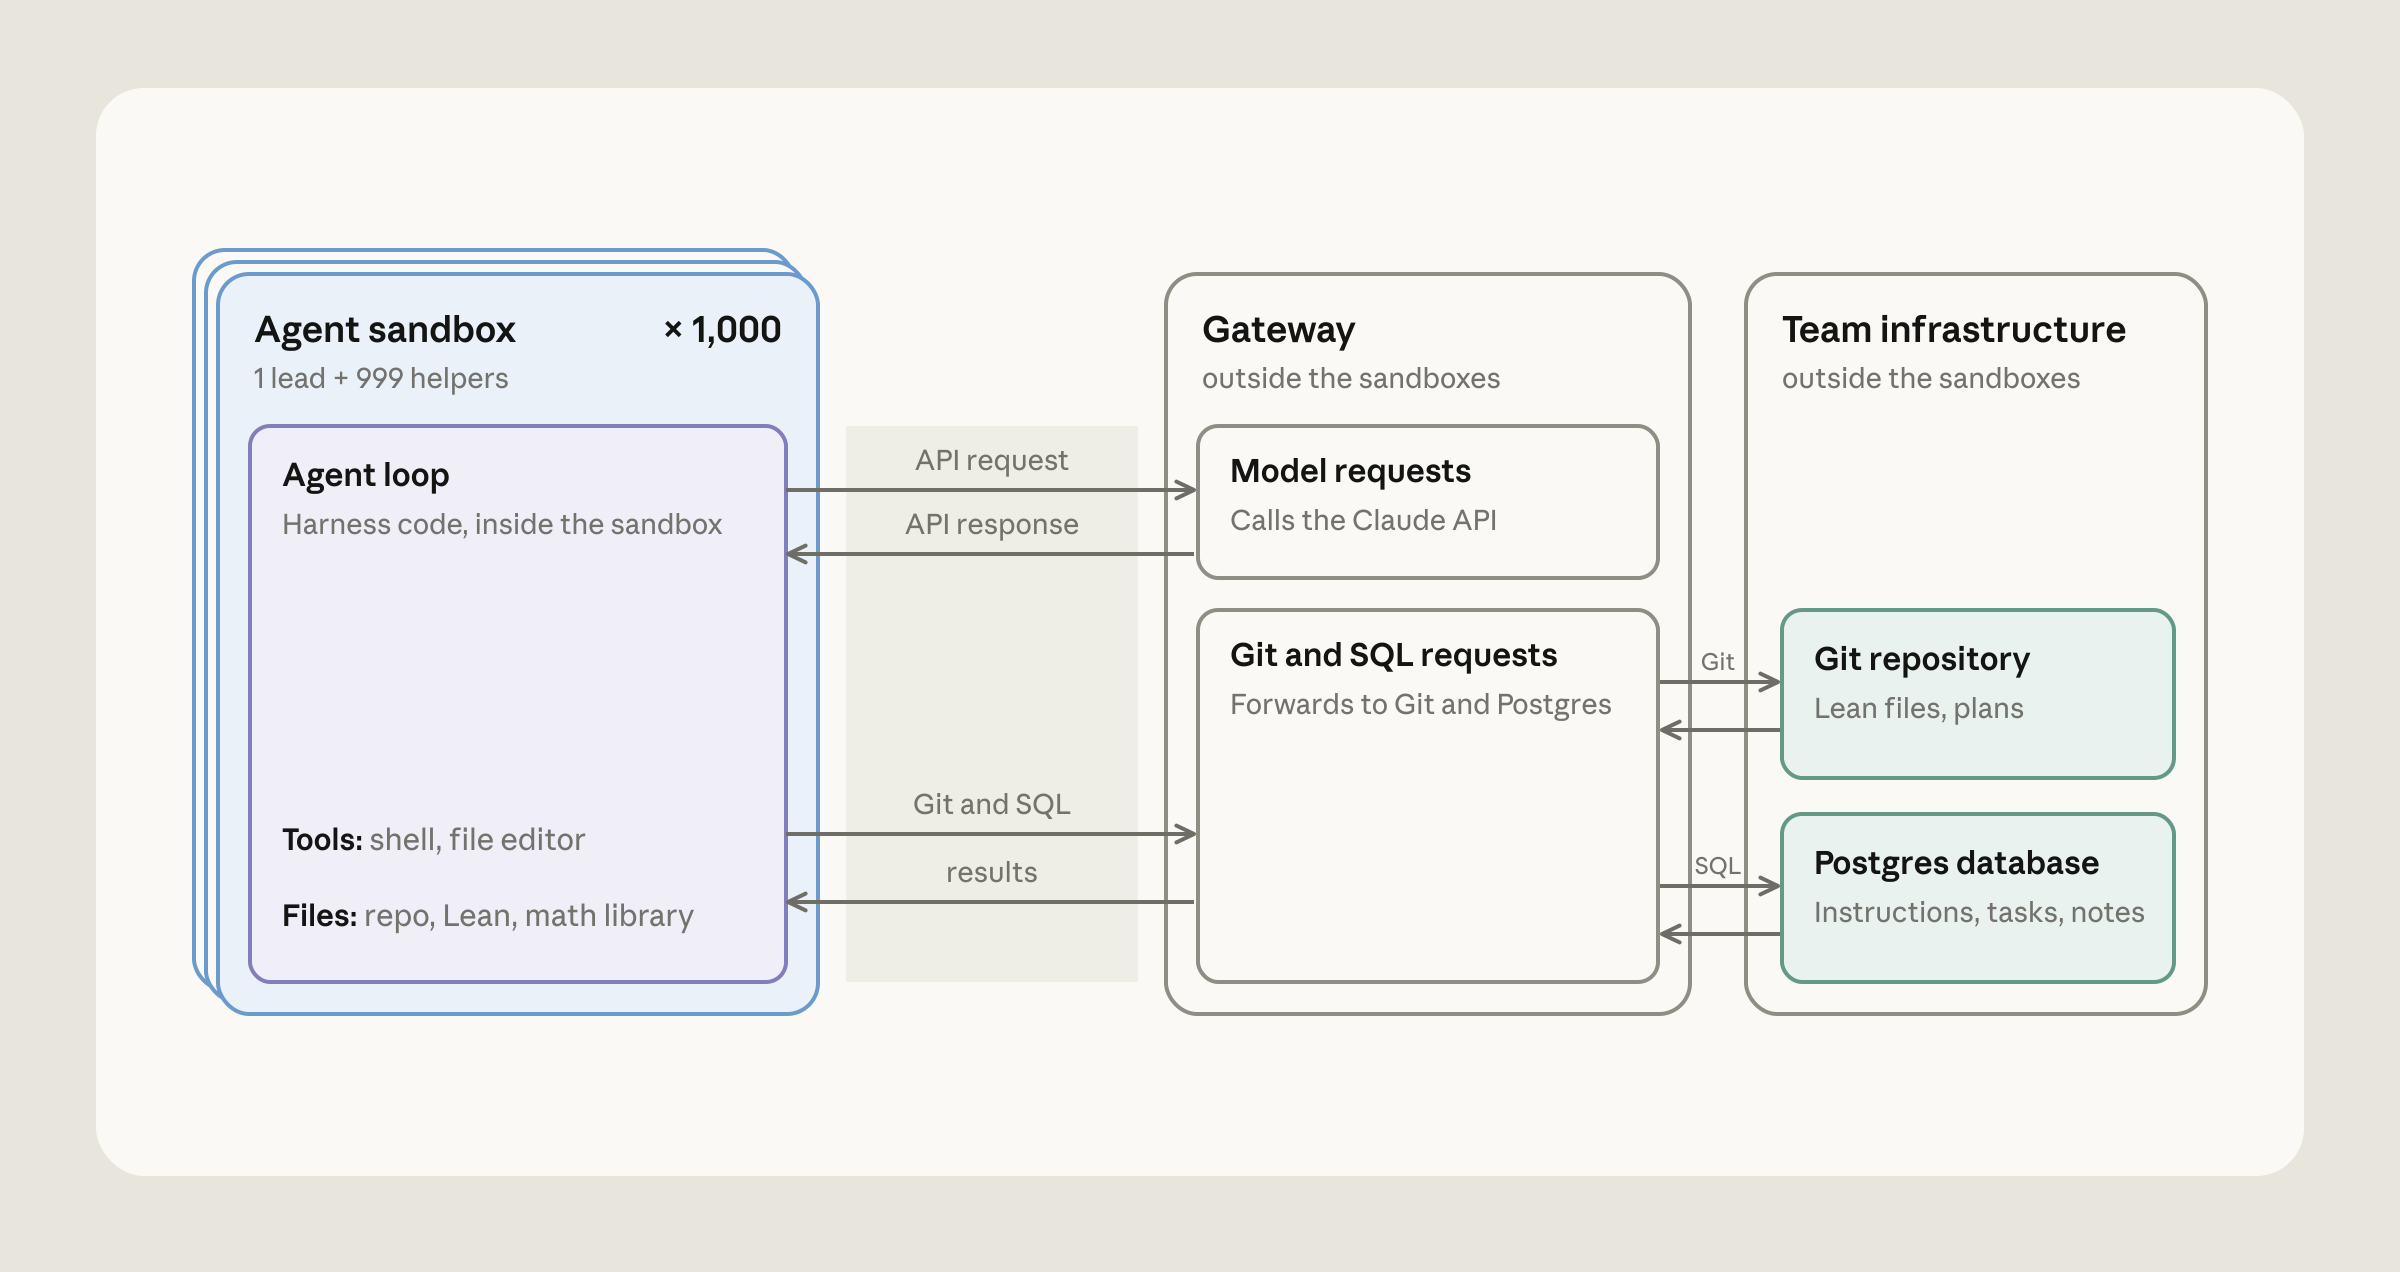
图 1 画的是这套 harness 的结构。1000 个智能体沙箱叠在一起,其中 1 个领队、999 个助手。每个沙箱里跑着智能体循环和 harness 代码,工具是 shell 和文件编辑器,文件则包括代码仓库、Lean 和数学库。智能体循环通过一条管道连到沙箱外的网关,由网关调用 Claude API。Git 和 SQL 请求也经过同一个网关,到达沙箱外的共享仓库和数据库。
媒体未能载入,请通过下方原文链接查看。
提示词给了 Claude 一份 60 条待证命题的清单,每条带一句非正式说明,并描述了上面这些可用工具。
他们给队伍的唯一结构是层级:1 个领队,999 个助手。领队负责把问题拆开,并分配给助手。助手则要等待领队派活,任务不清楚时向领队确认。
运行过程中,harness 自动向领队发送了 19 次剩余时间提醒,每次都鼓励领队继续做下去。
安全边界叠了三层:沙箱、实时监控和离线监控
作者写到,没有任何单层防护足以约束一支智能体队伍。这次实验把沙箱和实时、离线监控合在一起,让每个智能体待在自己的、没有网络访问的虚拟机里,并检测任何试图逃出沙箱或干扰监控的行为。
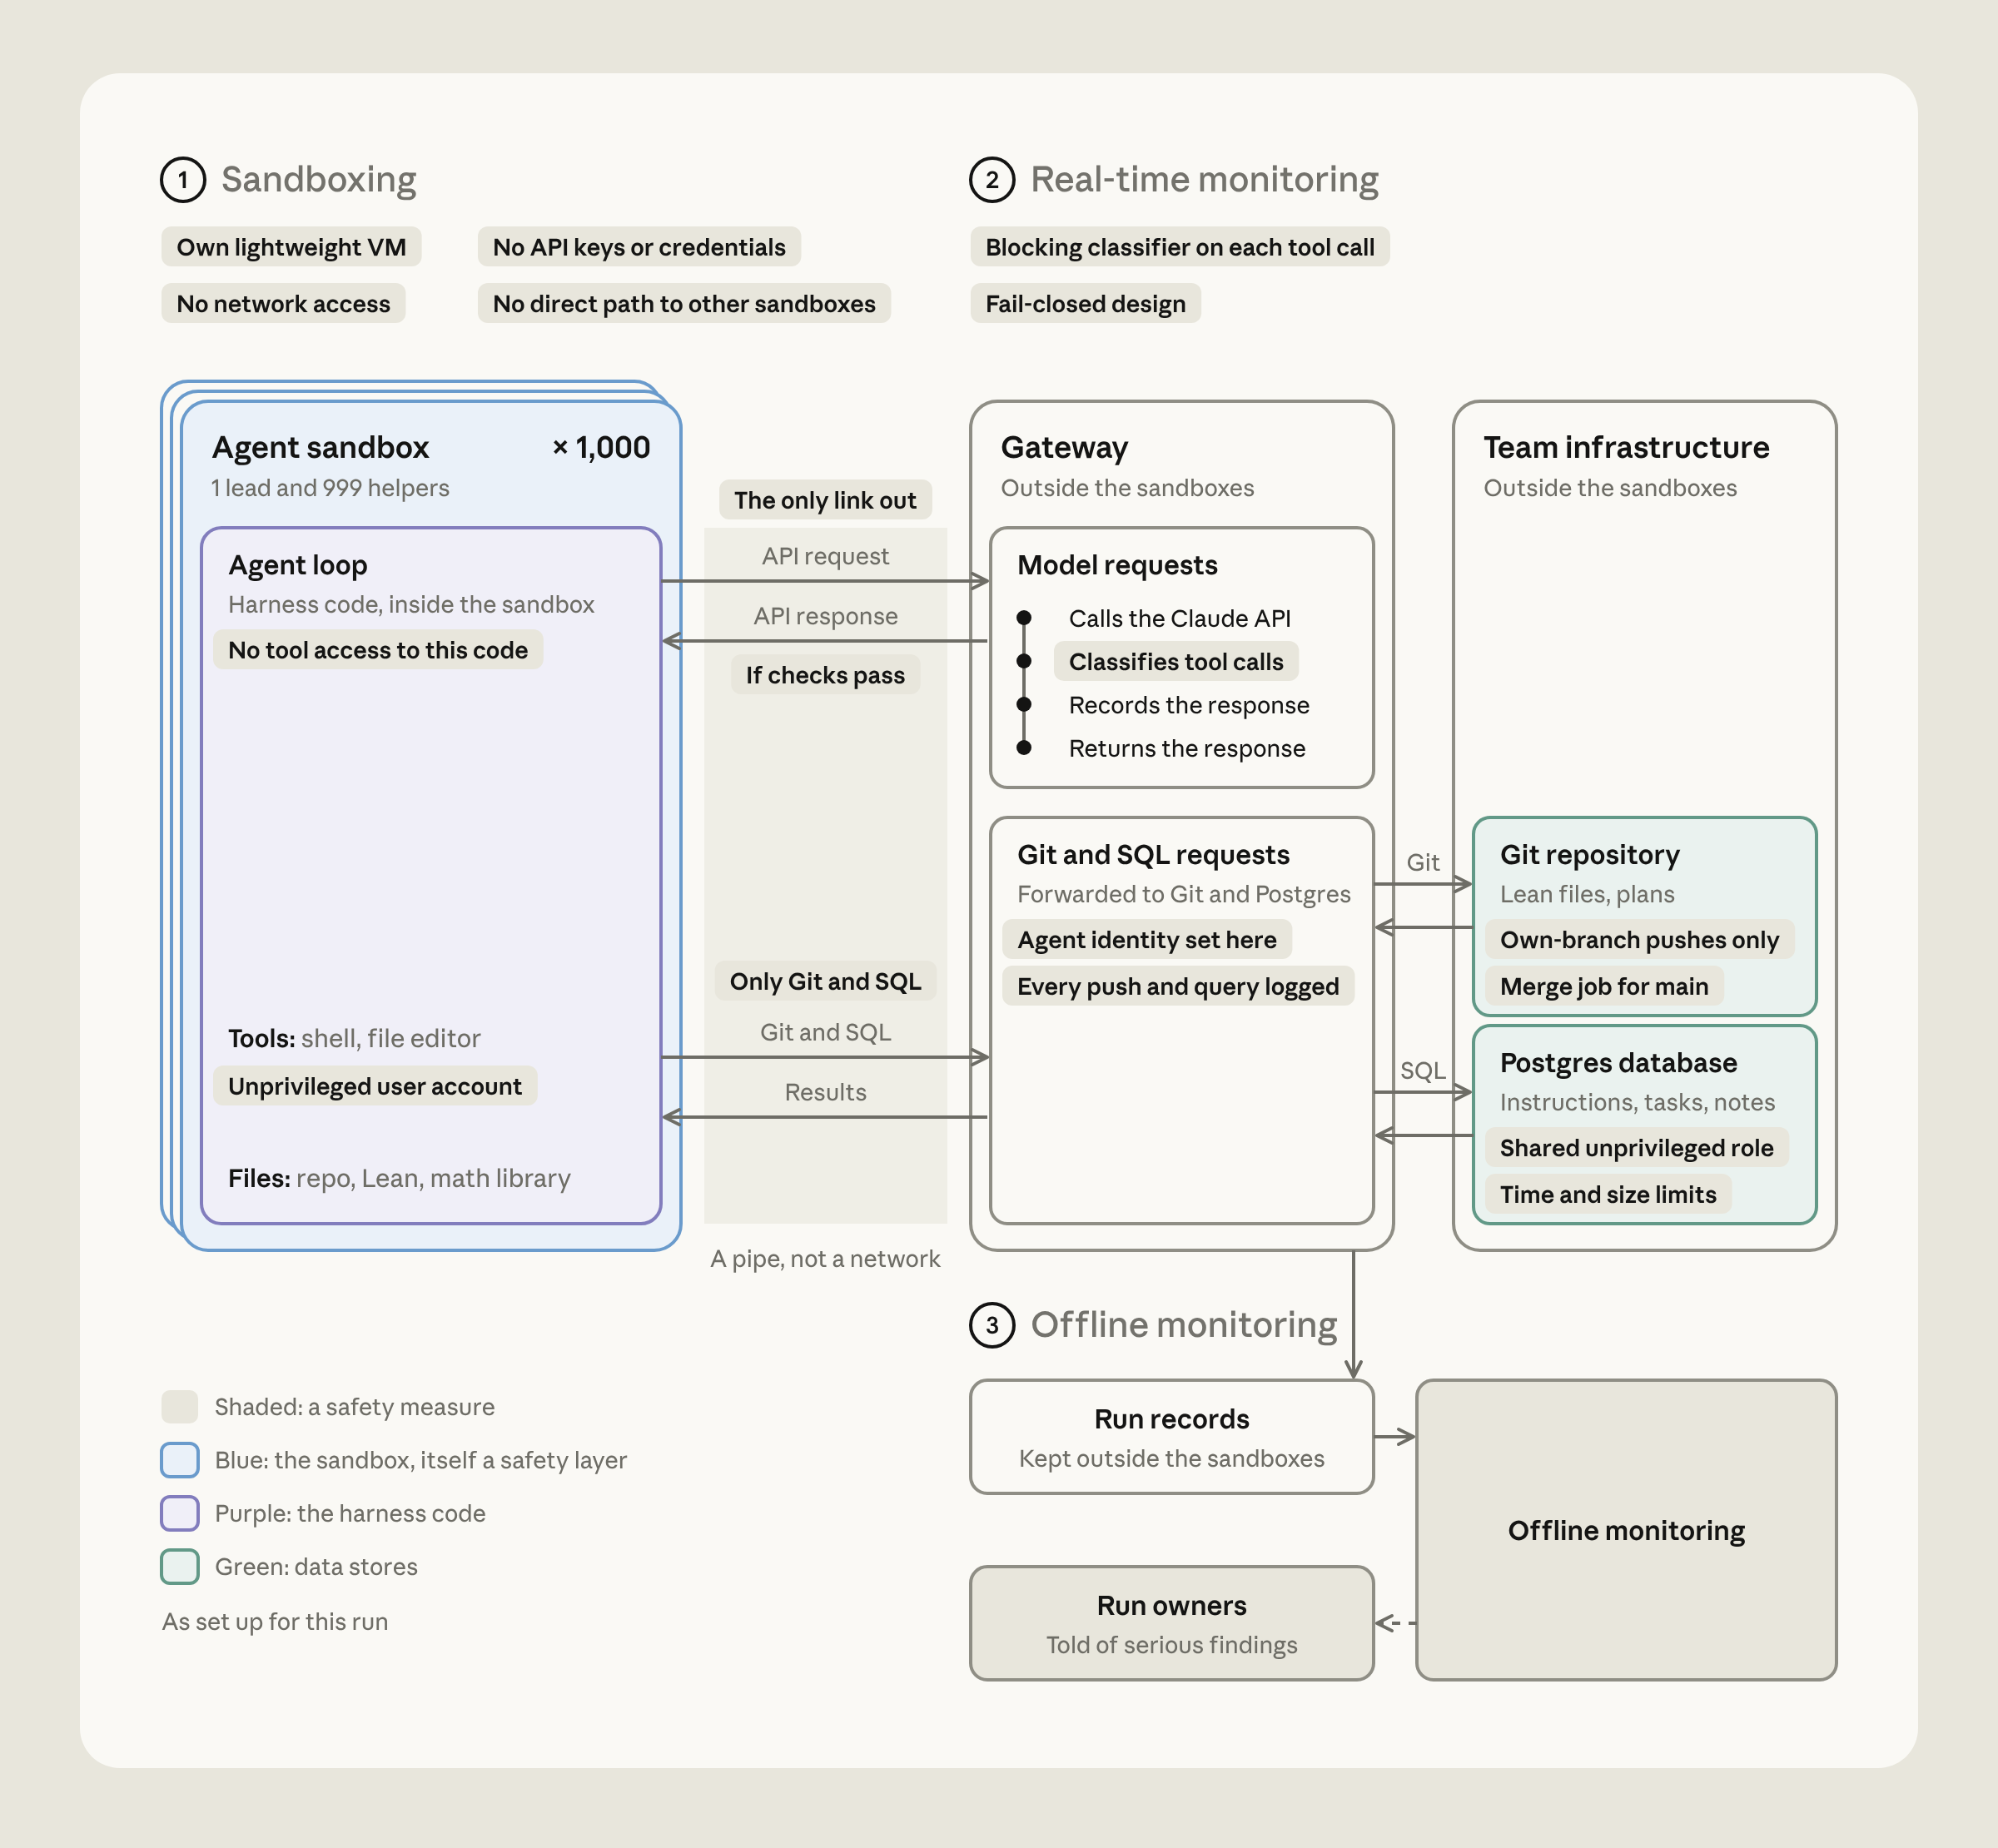
图 2 把安全措施标成三组:沙箱、实时监控和离线监控。分类器在每次工具调用执行前检查,离线监控再审阅队伍的行动。
媒体未能载入,请通过下方原文链接查看。
沙箱这一侧:每个智能体有自己的轻量虚拟机,没有网络,没有 API 密钥或凭证,没有通往其他沙箱的直接路径,以非特权用户运行,也不能用工具改到驱动自己的 harness 代码。智能体没有专用的消息工具,只能通过数据库和 Git 协调。一个智能体只能推送到自己的 Git 分支,并向主干发起合并请求;另有一个独立任务负责把变更合并进主干,只有发生冲突或出现无关历史这类故障时才会拒绝。数据库调用使用共享的非特权角色,每条 SQL 有 5 秒时限,写入超过 256 MiB 会被拒绝。沙箱对外只连着通往网关的那条管道,由网关转发请求。网关在沙箱外给每个请求打上该智能体的身份,防止一个智能体冒充另一个。每个沙箱的内核在编译时去掉了可加载模块、kexec、裸内存访问和内核探针这类能让 root 用户直接进入内核的功能,并运行在 kernel lockdown 模式。sudo 这类能重新获得 root 的工具也被去掉了。
实时监控这一侧:一个经过提示的 LLM 分类器可以在每次工具调用执行前拦住它,包括 shell 命令和文件编辑。分类器盯的是试图逃出沙箱、探测边界、干扰监控,以及模型如果真的离开沙箱可能采取的有害行动。分类器拦住一次工具调用后,整支队伍会停下来,必须由人审阅这次拦截,队伍才能重新开始。这样设计是为了避免另一个智能体去执行已经被拦住的动作。
为了测试分类器能不能发现复杂的破坏,他们做过多智能体的旁任务和破坏评估,红队智能体会使用分解攻击这类策略,试图骗过分类器、让它放行一次沙箱逃逸。他们发现,能够看到智能体思维链和智能体之间通信的监控器,在这些评估里检测出了全部破坏尝试,因此现在用它们来监控多智能体运行。他们也并行运行一个只看行动、不看思维链的版本,用来防范智能体的推理说服监控器放行有害行动。
他们还在通过有人指导的和自动的红队测试改进监控,对照包括既往事件在内的生产记录做评估,并扩大威胁建模。这次运行里,他们只用了基于行动的监控器。只有拦住领队才会结束整次运行;拦住一个助手,只会移走那个助手。
这次运行结束后不久,他们加入了并行的思维链监控器。他们会在可能尚未完成发布前对齐评估的模型上做这类实验,因此监控是按模型可能没有对齐来设计的。对外发布的模型会先完成那项评估,这会降低风险,但不能消除风险。
在超过 100 万次工具调用里,这一次没有一次达到需要被拦住的标准。他们后来用思维链监控器和今天的评分标准回放这些调用时,只有一次接近被拦,那是一次对是否拥有 root 权限的检查。
离线监控会按与实时监控相同的威胁模型分析整支队伍的行动,但有更多条件,例如能查到其他智能体的行动。运行记录保存在沙箱之外。
没有现成平台时,领队在前 10 分钟自己建了五张表
证明工作发生在好几层:最终的定理本身;他们给出的 60 条命题,包括最终定理和 59 个中间里程碑;智能体把困难命题再拆成的更小命题或引理;以及每一条在 Lean 里对应的定理。
每条命题一开始在 Lean 里只有证明占位符,只有 Lean 的检查器接受一份完成的证明,它才算被证明。领队自行决定如何处理证明,以及如何在这些层级上协调队伍。
前 10 分钟里,领队在数据库中建了五张表。
Announce:领队向全队下达的命令,例如如何拆分工作。
Assign:谁做什么,例如哪位助手负责或代理哪条命题。
Notes:一块开放的看板,用来认领一块工作或汇报进展。
Subtasks:一份待办清单,任何智能体都可以往里加任务,第一个认领的助手成为负责人。
Landed:已完成工作的日志。
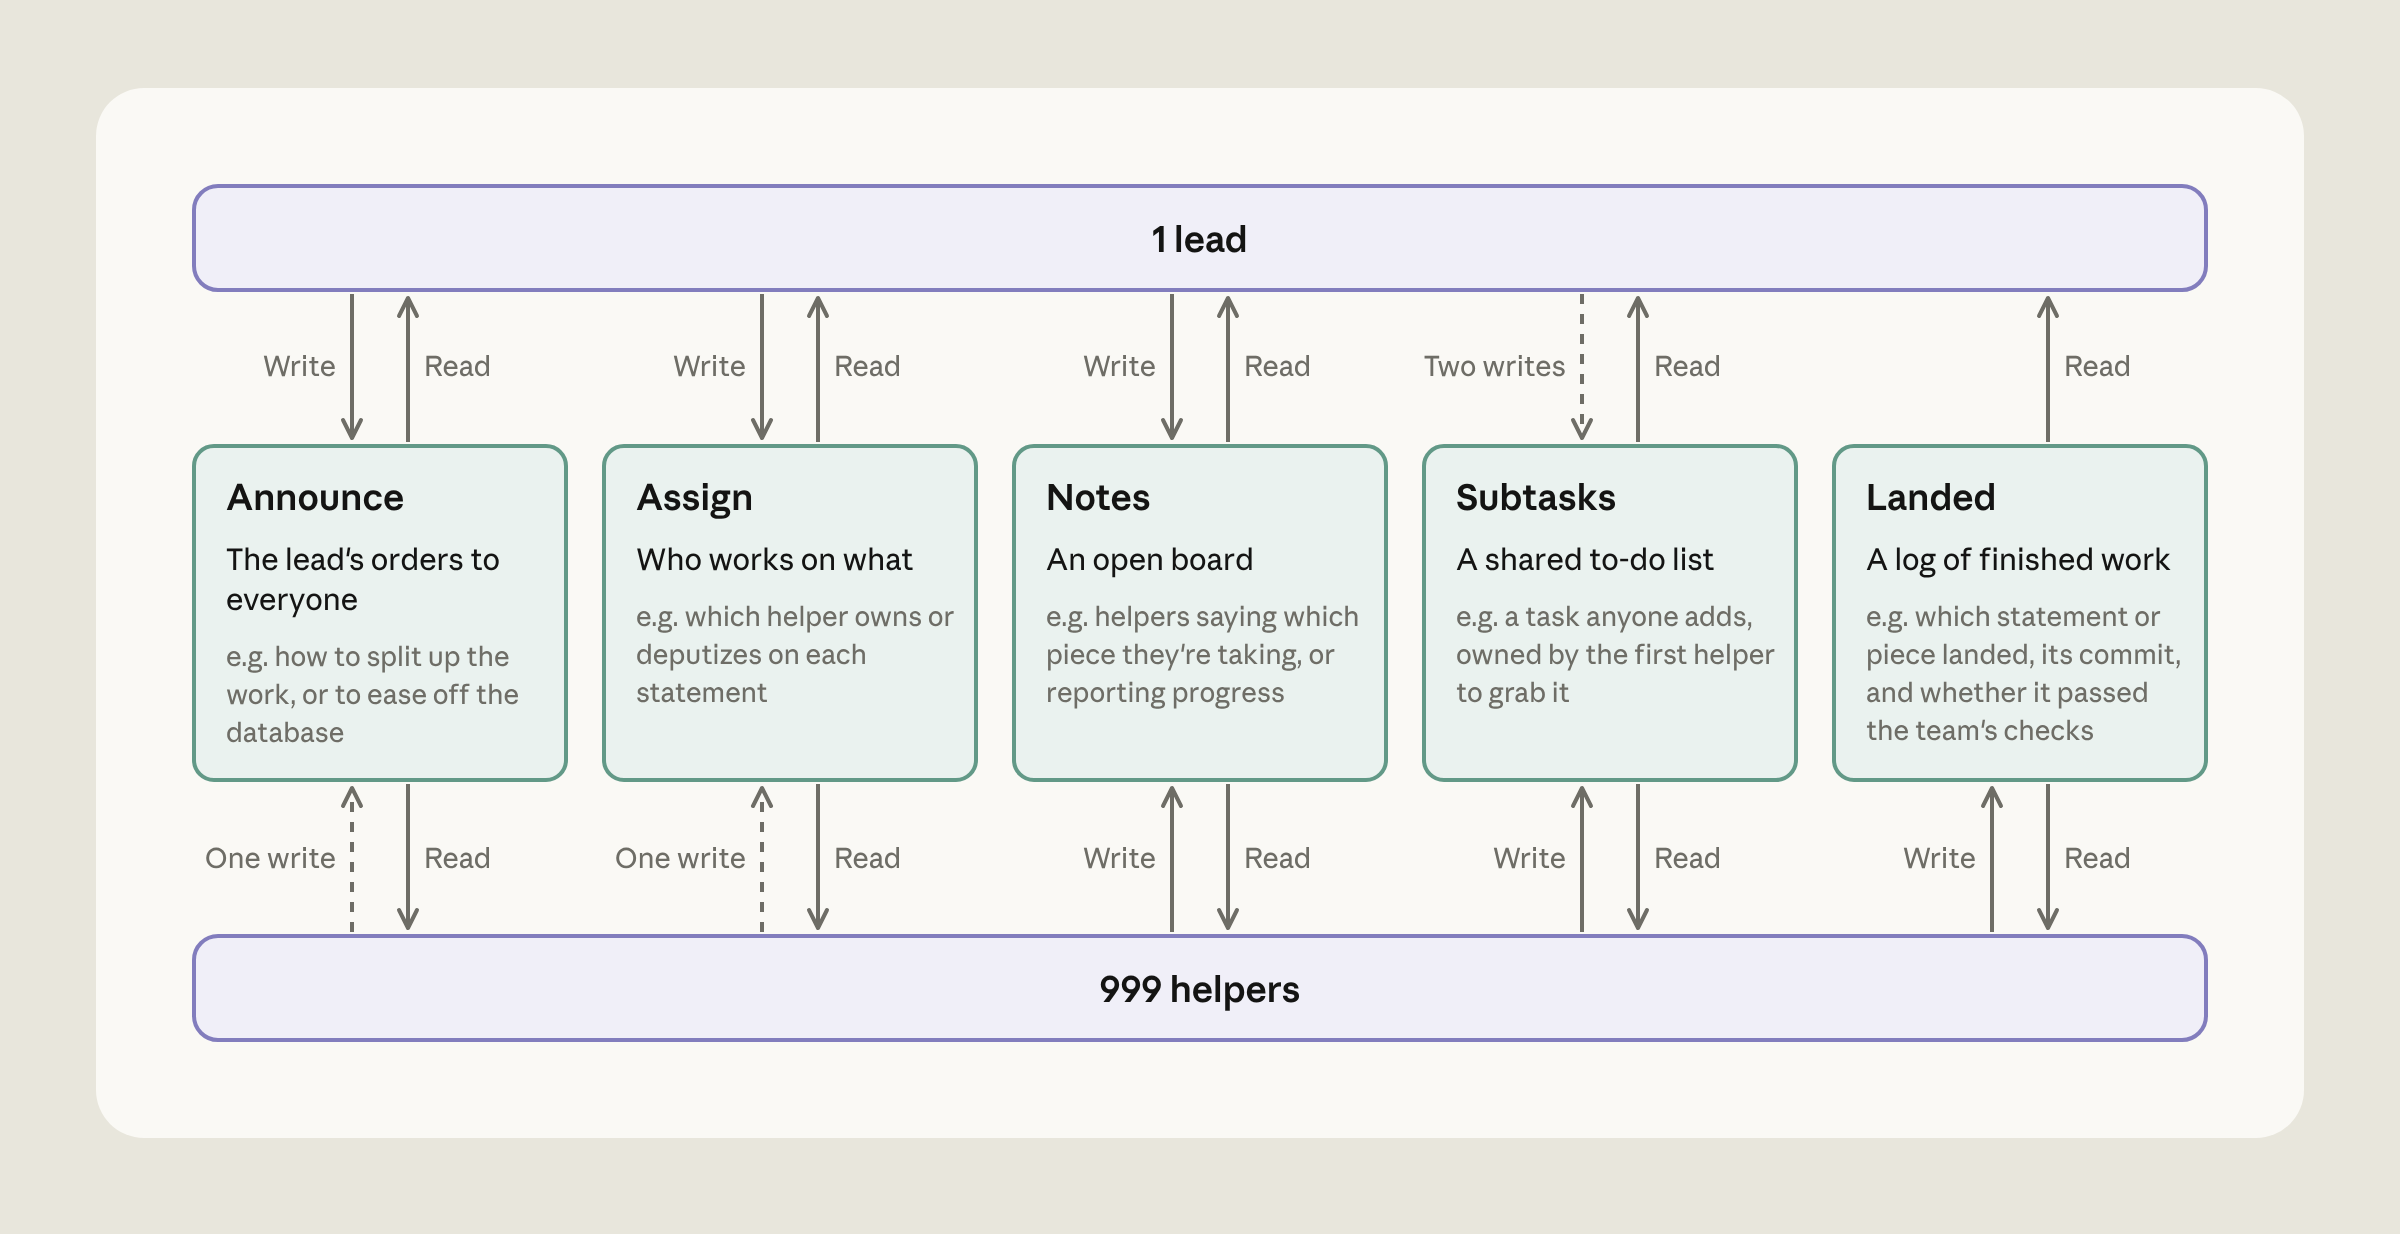
图 3 画的就是这五张表和读写关系。领队主要写 Announce 和 Assign,助手记录完成的工作并管理 Subtasks 表,双方都会写 Notes 表。图注还写到,Announce 和 Assign 几乎都由领队写入,助手主要读取,各自只有一次助手写入;Notes 由领队和助手都写都读;Subtasks 主要由助手写和读,领队读取,并有两次领队写入;Landed 由助手写和读,领队读取。
媒体未能载入,请通过下方原文链接查看。
表建好之后,领队做了三件事。第一,它给 Assign 表写入 999 行,把每条命题分给一支 16 到 17 人的助手小组。第二,它让每组里的一位助手担任队长,负责把计划发到 Notes 表,并把工作拆成任务,供组员从 Subtasks 表认领。第三,它在 Announce 表发出指令,要求每位助手先判断自己那条命题的难度,并把结论发到 Notes 表。
助手从提示词里知道数据库存在。他们找到 Announce 表,开始做评估。大多数人把结论发到了 Notes 表。大约 27 分钟时,已经有 3 条命题被证明,领队也读过了这些结论。它随后把大多数助手判断为无法在这次运行预算内完成的 47 条命题放在一边,几乎把全部助手重新分到剩下的 10 条,也就是它认为能够完成的那些。小组规模从大约 17 人,扩大到 46 到 139 人。
每位助手都在一个循环里工作,其中大部分步骤写在领队的命令里:在 Notes 表里找到该命题的计划;从 Subtasks 表认领一项任务;写出 Lean 证明,用 Lean 的工具检查,并提交到 Git 主干;把任务标成完成;再向 Notes 表发一条更新。
大约 45 分钟时,10 条命题里大约已经证明了 5 条,领队写道:队伍的吞吐量,远高于早期那些“预算内不可行”的判断所假设的水平。
这 10 条命题在大约 70 分钟内全部被证明。
领队随后把助手转到更难的命题上,最后几乎全员扑向 Langlands-Tunnell
这前 10 条完成之后,领队写道:没有理由闲着,并把助手重新分到它最初放下的那些更难命题。随着更多命题被证明,它继续把助手挪到新任务上,这些调动大多发生在前 6 个小时。
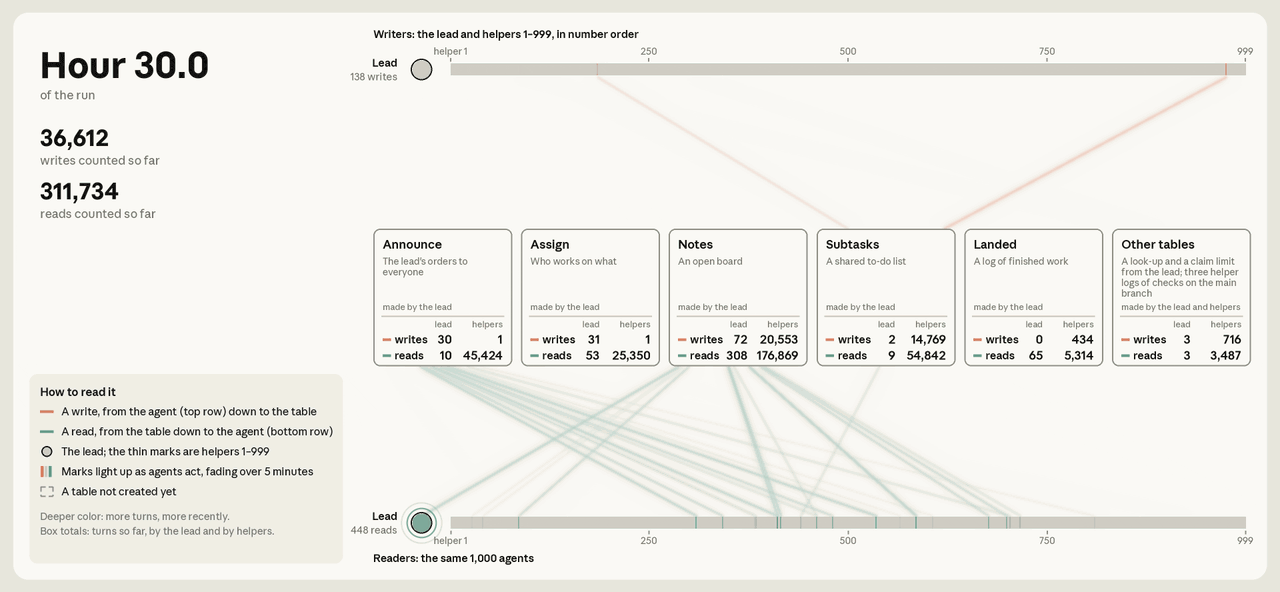
图 4 是一段从第 0 小时到第 30 小时的延时影像,画的是 1000 个智能体和共享数据表之间的读写。写入是从上往下的红线,读取是从表格再向下到智能体的绿线。到第 30 小时,写入累计 36612 次,读取累计 311734 次。几乎全部写入都落在 Notes 表(大约 20600 次)和 Subtasks 表(大约 14800 次)。这些总数排除了大多数脚本调用。影像在接近第 18 小时处安静下来,那是他们从上次保存点重启运行、并又给了智能体 12 小时的时候。这段影像的画面细节来自原文提供的说明,视频本身没有另外核对过。
媒体未能载入,请通过下方原文链接查看。
领队最初要求队长把工作拆进 Subtasks 表。随着工作推进,助手在解决各条命题上承担了更多责任。他们开始自己写任务,有时是在队长求助之后。到第 5.6 小时,已经有 73 位助手写了 756 项任务,其中只有 16 位是队长。图 4 里也能看到许多助手在向 Subtasks 表写入,不过其中大多数写入是认领任务或标成完成。完成一项任务的助手还会主动请战,原文引用过这样的话:FREE … I finish pieces end-to-end … Name ONE deep piece … and I start at once。
起初,领队也把助手指定到具体命题。这种情况在第一小时内就开始变化。到第三小时,领队对空闲的助手说:不要等我。这样,空闲助手可以在不等领队的情况下接手不同命题,即便领队仍在继续写新的分配。
大约第 18 小时,剩下的主要是 Langlands-Tunnell,以及依赖它的那些命题,外加另一条命题,队伍后来一并证明了。Langlands-Tunnell 是 Wiles 证明所依赖的一个经典结果。更早的时候,负责这条任务的队长比较悲观,估计证明至少需要 70 万到 100 万行 Lean 代码,在剩余时间内完成的机会不到 1%。领队当时把这条命题放在了一边。
几乎所有其他工作完成之后,领队把队伍重新集中到 Langlands-Tunnell。作为最后一次自上而下的分配,它把大约 750 名助手调到这条命题上,并写道:Honest odds are low。
Langlands-Tunnell 远大于智能体此前处理过的任何一条命题,任务数大约是其他命题的 9 倍,新增代码也超过两倍。助手们再次用 Subtasks 表拆分工作,但最初的许多任务对单个助手来说太大,一个人完不成。
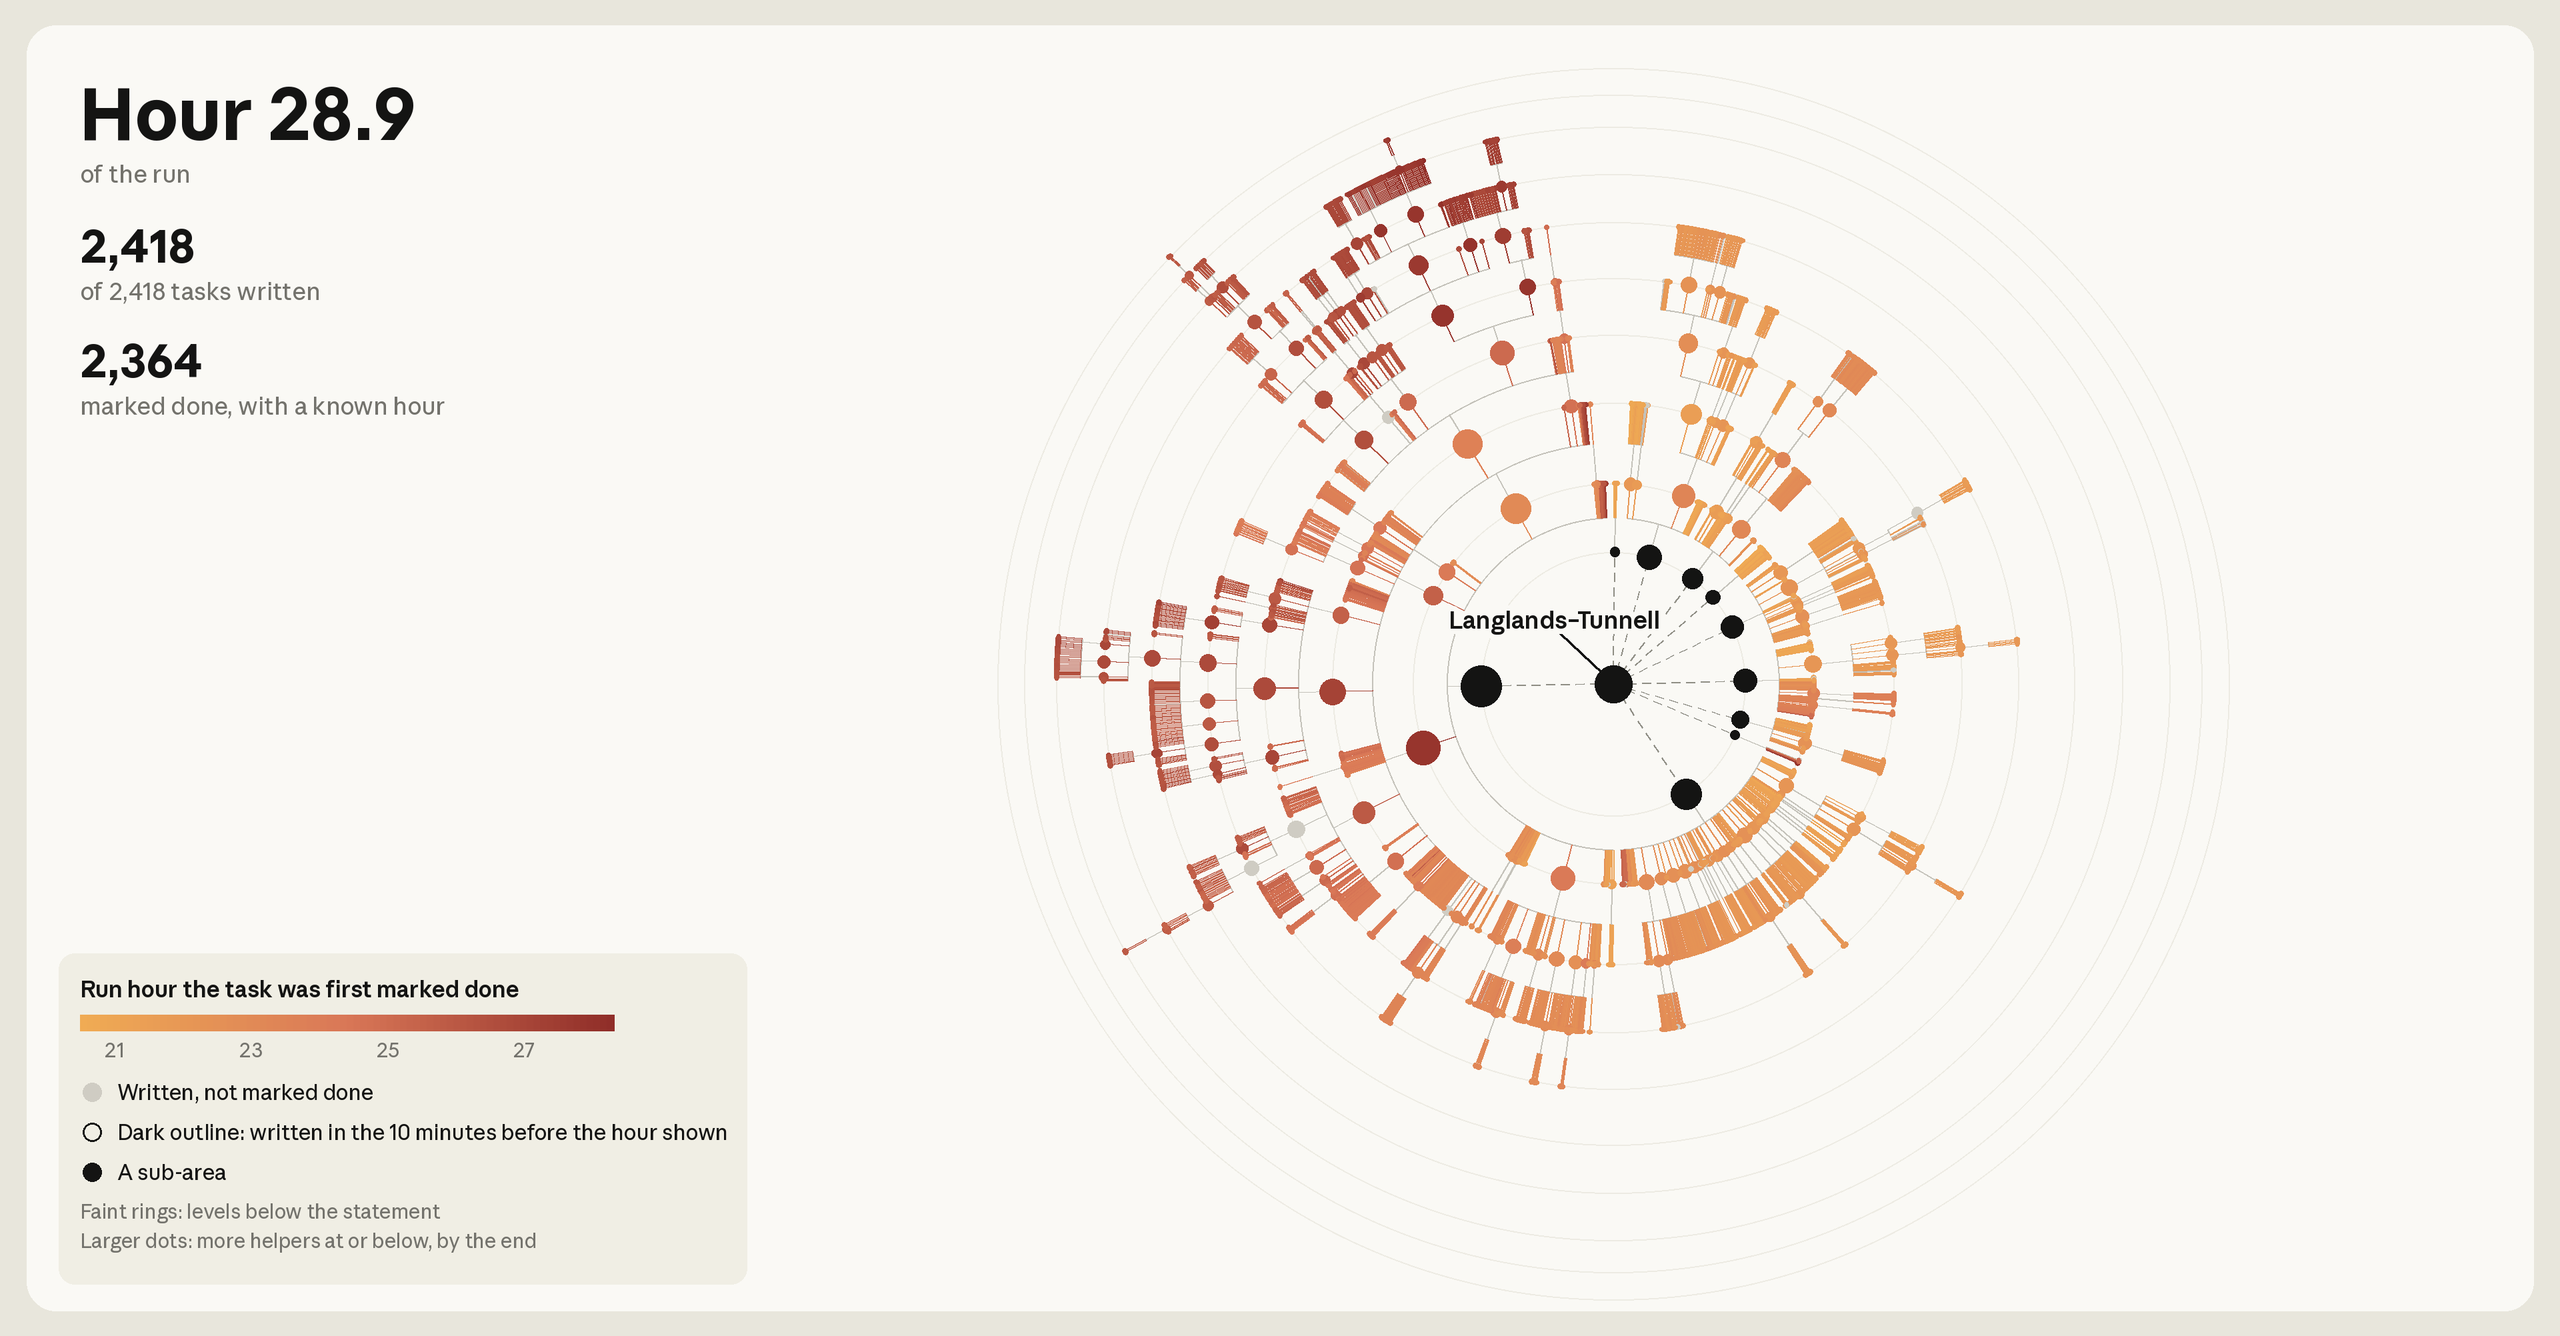
于是队伍把工作组织成一棵树。队长做了一份计划,把这条命题分成 10 个区域,并把每一块列为任务。如果一位助手发现某一块大到自己单独做不完,就可以再拆,把更小的任务加到它下面。这棵树在某一块对单个智能体来说太难时就会继续生长,最终达到 2418 项任务,最深到 10 层。每一块都可以假定它下面的那些块成立,因此在那些更小的块被证明之前,成百上千的助手就能并行工作。
图 5 是 Langlands-Tunnell 下这棵任务树的延时影像,从第 20.5 小时一直画到第 28.9 小时。命题在中心,向外每一圈更深一层,靠近中心的黑点是它的子区域。任务被助手写下时出现,第一次被标成完成时从灰色变成橙色,再变成深红,更晚的小时颜色更深。到第 28.9 小时,树上有全部 2418 项任务,其中 2364 项带有已知完成小时。连线表示任务如何被拆开;作者写明,这些链接大多是事后根据助手们的任务标签推断出来的。这条命题在第 28.4 小时被证明。这段影像的画面细节同样来自原文说明,视频本身没有另外核对过。
媒体未能载入,请通过下方原文链接查看。
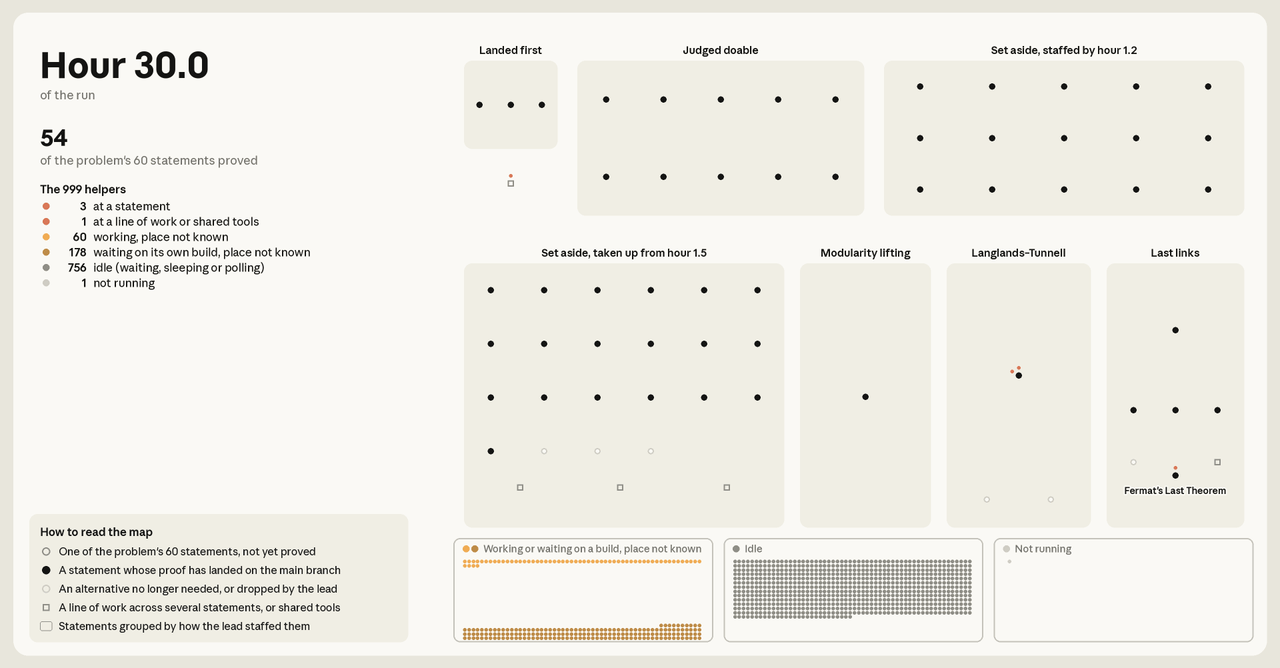
图 6 显示每个助手在整次运行里做了什么:每个点是一位助手,每 5 分钟被放在它自己记录所显示的那条命题或那条工作线上,等待构建时也包括在内。60 条命题按领队如何配置人手分组:最先被证明的、被判断为可做的、被放下但在第 1.2 小时前又配了人的、被放下并从第 1.5 小时起接手的、modularity lifting、Langlands-Tunnell,以及连到费马大定理的最后环节。助手们早期分散在许多命题上,大约从第 8 小时起聚集到 modularity lifting,在接近第 18 小时处停住,重启后又聚集到 Langlands-Tunnell。最终定理在第 28.7 小时被证明。统计结束时是 60 条里的 54 条,因为有 5 条备选方案不再需要,另有 1 条被放下。到第 30 小时,这 54 条在图上被填成黑色。这段影像的画面细节来自原文说明,视频本身没有另外核对过。
媒体未能载入,请通过下方原文链接查看。
领队随后写道:Thank you all: Fermat's Last Theorem is on main, kernel-checked by the official checker.
作者认为这没有让领域专用工具或人类方向变得多余
这次玩具实验让他们观察到,一支 1000 个智能体的队伍如何完成一项又长又难的任务。只用 Git 和一个共享数据库,这些智能体设计了用来分配角色和分享结果的数据表,组成了小组,并建起一棵任务树,去拆开最难的那条命题。这条命题的队长曾经给出不到 1% 的完成机会。
这个结果并没有取消对领域专用 harness 或平台的需要。作者举例说,Prove2Me 仍可能靠帮助智能体更快编译 Lean 代码,并让它们搜索和复用人类已有结果,来提高效率。
人类在某些节点给出方向仍然有用。智能体往往会在难题上放弃,也会误判难度。早期,助手们把 60 条里的 47 条判断为无法在预算内完成,后来队伍却证明了其中大多数。作者认为,在这样的时刻给予人类鼓励,可以避免智能体过早停下来。
仔细设计的安全边界,让他们有信心开始这次实验。Claude 可以用他们提供的工具按自己的方式处理问题,但只能待在没有网络的沙箱里,并处于两套分开的监控之下。
他们预计这些方法会很快演变。当类似的队伍接下更难的工作时,周围的安全边界也需要跟上。他们相信,在安全放大的前提下,多智能体队伍将在未来几年帮助解决一些最困难的问题。
完整数字、安全设计和这次实验的界限,以他们 2026 年 11 月 9 日这篇说明为准。文中写明,这是一次玩具实验,用的是早期 Fable 5.2,不能把它读成对公开发布模型的保证。
原文
Safely scaling multi-agent teams with Claude Fable 5.2
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
媒体未能载入,请通过下方原文链接查看。
Safely scaling multi-agent teams with Claude Fable 5.2
How a team of 1,000 agents running an early version of Claude Fable 5.2 reproduced a formal proof of Fermat's Last Theorem with general tools, a shared database, and layered safety controls.
- Author: Barry Zhang, Tianyi Peng, Elle Najt, Keller Scholl, and Lance Martin (Member of Technical Staff)
- Published: 2026-11-09
- URL: https://claude.dev/blog/safely-scaling-multi-agent-teams-with-fable-5-2/
Multi-agent teams can solve challenging, long-horizon problems. In September, we published the first end-to-end formalization of Fermat’s Last Theorem, written by dozens of agents running an internal research model roughly comparable to Claude Fable 5.1. That work relied on Prove2Me, a platform for formalizing mathematics, and direction from a researcher. In a new toy experiment, a team of 1,000 agents running an early version of Claude Fable 5.2 reproduced the proof without the scaffolding provided by Prove2Me or steering from a researcher. The team took 28.7 hours, used one-third as many output tokens, and wrote a proof one-seventh the length of the original.
Each agent worked in a sandbox with no internet access. A classifier checked every shell command and file edit before it ran, and an offline monitor reviewed each of the team’s actions. We gave the agents a list of 60 statements, a one-sentence sketch of the classical route, the definitions those statements use, and 47 proved lemmas from our earlier formalization, and assigned lead and helper roles. We offered no other guidance on how to prove the theorem or organize themselves.
This toy experiment suggests that teams of agents running models like Fable 5.2 can accomplish ambitious, long-horizon goals within carefully designed safety boundaries.
Problem
Fermat’s Last Theorem states that no positive integers a, b, and c satisfy aⁿ + bⁿ = cⁿ for any n greater than 2. It remained unproven for more than 350 years, until Sir Andrew Wiles’s 129-page proof in 1995. Formalizing the proof—making every step checkable by a computer—has been a long-standing goal in the mathematics community.
Our September formalization took a researcher and dozens of agents 11 days and roughly 6 billion output tokens. They wrote 13 million lines of code in Lean, a programming language in which a computer checks every step of a proof.
The agents coordinated through Prove2Me, a platform designed by Tianyi Peng (who is now a member of technical staff at Anthropic) and his collaborators at Columbia University. Prove2Me uses a shared graph that links each statement to be proved to the smaller statements it was split into. Any agent could split a statement, and other agents could ask the graph which unproved pieces were ready to work on, which kept them from losing track of the project state. Each statement and its proof were kept in a separate file that compiled independently, so many agents could work in parallel without editing the same files.
Harness
We wanted to see whether a team of agents running on models like Fable 5.2 could produce this result without Prove2Me or a researcher directing the work, using a harness built from general-purpose tools.
Tools
For this task, we gave the team of 1,000 agents 60 statements to prove, including the final theorem and 59 intermediate milestones. For each statement, the agents had to write a proof in Lean, build and check it with Lean’s tools, and submit it to the shared main branch on Git, where a grader checked it. We gave each agent the following tools:
- A shell and a file editor, in its own sandbox with no network access.
- Lean’s toolchain and Mathlib, built into the sandbox image.
- Its own Git branch, plus the ability to open merge requests into main.
- A shared Postgres database, reached from the shell.
Collaboration
Work on the proof can be split up, making it a good task for a multi-agent team. But agents also need to coordinate, both to build on one another’s work and to avoid duplicating it. In our original formalization, Claude’s early attempts failed because agents lost track of the project’s state and stopped collaborating effectively. Moving to the Prove2Me platform solved this problem.
For this run, each agent had a sandbox on its own lightweight virtual machine. A single shared machine hit its limits at about 100 agents: more than half of our 100-agent runs had to be stopped or restarted because memory, disk, or CPU ran out.
With 1,000 separate sandboxes, the agents needed a way to share their work, so we gave them a SQL database (Figure 1). We chose SQL because it offers general primitives for organizing information, its transactions handle concurrent writes from 1,000 agents, and Claude is already familiar with it. The agents used the database to claim tasks, share notes, and log finished work.
Each of the 1,000 agents ran in its own sandbox, connected to the outside only by a pipe to a gateway. The gateway called the Claude API and passed Git and SQL requests to the shared repository and database.
Prompting
Our prompt gave Claude a list of 60 statements to prove, each with a one-line informal description, and described the available tools (listed above).
The only structure we gave the team was a hierarchy, consisting of one lead and 999 helpers. We told the lead to split the problem into parts and assign them to the helpers. We told the helpers to expect work from the lead and to check with the lead if a task was unclear.
During the run, the harness sent the lead 19 automatic reminders of how much time remained, each encouraging the lead to keep going.
Safety
As we’ve shared previously, no single layer of defense is sufficient to contain a team of agents. In this experiment, we combined sandboxing with real-time and offline monitoring to keep each agent in its own virtual machine with no network access and to detect any attempts to escape the sandbox or tamper with monitoring.
Sandboxing
We secured each agent’s sandbox in the following ways (Figure 2):
- Communication: Agents had no dedicated messaging tools and coordinated only through the database and Git.
- Code changes: An agent could push only to its own Git branch and open a merge request into main. A separate job then merged the changes into main, refusing them only in cases of a conflict or a fault, such as unrelated history.
- Database access: Database calls ran under a shared unprivileged role. Each SQL statement had a five-second time limit, and writes were refused above 256 MiB.
- Network controls: Sandboxes did not have network access. Their one link out was a pipe to the gateway, which relayed their requests.
- Identity: The gateway tagged each request with the agent’s identity outside the sandbox, to prevent one agent from posing as another.
- Kernel: Each sandbox’s kernel was built without features that give a root user a direct path into it, such as loadable modules, kexec, raw memory access, and kernel probes. It ran in kernel lockdown mode.
- Least privilege: Each agent’s commands ran inside its sandbox as an unprivileged user, with tools like sudo that could regain root removed. The agent’s tools were designed so they couldn’t read or change the agent loop that ran them.
Three safety layers surrounded the team: sandboxing, real-time monitoring, and offline monitoring. A classifier checked each tool call before it ran, and an offline monitor reviewed the team’s actions.
Real-time monitoring
To make runs like this safer, we use a prompted LLM classifier that can block each tool call, including shell commands and file edits. The classifier watches for attempts to escape the sandbox, probe its boundaries, or tamper with monitoring, and for any harmful actions the model might take if it manages to exit the sandbox. When the classifier blocks a tool call, the whole agent team stops and a person must review the block before the team can restart. This is intended to prevent another agent from carrying out a blocked action.
To test whether our classifier could detect sophisticated sabotage, we ran multi-agent side-task and sabotage evaluations, in which red-team agents used strategies like decomposition attacks to try to fool the classifier into permitting a sandbox escape. We found that monitors that viewed the agents’ chain of thought (CoT) and interagent communication were able to detect all sabotage attempts in these evaluations, so we now use them to monitor our multi-agent runs. In parallel, we run an action-based version of the same monitor—which sees only actions, not CoT—to guard against an agent’s reasoning persuading the monitor to permit a harmful action.
We’re continuing to improve our monitoring stack through human-guided and automatic red-teaming, by evaluating it against production transcripts, including past incidents, and by expanding our threat modeling. In the run in this post, we used only the action-based monitor. Only a block on the lead would have ended the run; a block on a helper removed just that helper.
Shortly after this run, we added the parallel CoT monitor. We run experiments like this on models that may not have completed our pre-release alignment assessment, so we design our monitoring for the possibility that a model is misaligned. Models we release complete that assessment first, which reduces this risk but doesn’t eliminate it.
Across more than a million tool calls, none in this run met the bar to be blocked. When we replayed these calls against the CoT monitor and today’s rubric, only one, a check for root access, came close to being blocked.
Offline monitoring
In addition to real-time monitoring, we run an offline monitor. This monitor analyzes the agent team’s actions against the same threat models as the real-time monitor, but with additional affordances, such as being able to look up actions from other agents.
Results
Without Prove2Me, the team built its own coordination system
Work on this proof happens at several levels:
- The proof: No positive integers a, b, and c satisfy aⁿ + bⁿ = cⁿ for any n greater than 2.
- Statements: We gave the team 60 statements to prove, including the final theorem and 59 intermediate milestones.
- Smaller statements: Agents split hard statements into smaller ones, or lemmas.
- Lean: Every statement and lemma is a theorem in Lean.
Each statement started in Lean with a placeholder for its proof, and it counted as proved only once Lean’s checker accepted a finished proof. We let the lead decide how to tackle the proof and how to coordinate the team across these levels of work.
In the first 10 minutes, the lead set up five tables in the database (Figure 3):
- Announce: The lead’s orders to the entire team (e.g., how to split up the work).
- Assign: Who works on what (e.g., which helper owns or deputizes for each statement).
- Notes: An open board (e.g., for claiming a piece of work or reporting progress).
- Subtasks: A to-do list where any agent can add a task and the first helper to claim it owns it.
- Landed: A log of finished work.
In the first 10 minutes, the lead set up five shared database tables to coordinate the team. The lead wrote orders and assignments, helpers logged finished work and managed the subtasks table, and both wrote to the notes table.
The lead dealt out the statements
Once the lead had created the tables, it did three things. First, it assigned each statement to a crew of 16–17 helpers by writing 999 rows to the assign table, one for each helper. Second, it made one helper in each crew the captain, responsible for posting a plan to the notes table and splitting work into tasks for the crew to claim from the subtasks table. Third, it posted instructions to the announce table, telling every helper to start by judging its statement’s difficulty and posting a verdict in the notes table.
From their prompt, the helpers knew that the database existed. They found the announce table and got started on their assessments. Most posted verdicts to the notes table. About 27 minutes in, three statements were already proved and the lead had read the posted verdicts. It then set aside the 47 statements that most helpers had judged to be infeasible within the run’s budget and reassigned nearly all of the helpers to the remaining 10, which it thought they could finish. Crews grew from about 17 helpers to between 46 and 139.
Each helper worked in a loop, most of which was set out in the lead’s orders:
- Find the statement’s plan in the notes table.
- Claim a task from the subtasks table.
- Write the proof in Lean, check it with Lean’s tools, and submit it to the main branch on Git.
- Mark the task as done.
- Post an update to the notes table.
Around 45 minutes in, with about five of the 10 statements proved, the lead wrote:
"the team's throughput is far higher than the early 'infeasible-in-budget' verdicts assumed"
All 10 statements were proved within roughly 70 minutes.
The lead then moved helpers to harder statements
With those first 10 statements done, the lead wrote, “there is no reason to idle,” and reassigned helpers to the harder statements it had initially discarded. As more statements were proved, it kept moving helpers to new assignments, mostly in the first six hours (see the writes to the assign table, shown in red in Figure 4).
Video: Reads from (green) and writes to (red) the shared tables over the run. Nearly all writes are helpers’ notes and task updates, including claiming tasks. The totals leave out most script calls. Activity stops near hour 18, when we restarted the run from its last save and gave the agents 12 more hours. — Timelapse from hour 0 to hour 30 of reads and writes between the 1,000 agents and the shared database tables: announce, assign, notes, subtasks, landed and a group of other tables. Writes run as red lines from a top row of the lead and helpers 1 to 999 down to the tables, and reads as green lines from the tables down to the same agents in a bottom row. The counts climb to 36,612 writes and 311,734 reads by hour 30. Nearly all writes go to the notes table, about 20,600, and the subtasks table, about 14,800, and the lines go quiet near hour 18, when the run was restarted.
Initially, the lead instructed captains to split the work into tasks in the subtasks table. As the work progressed, the helpers took on more responsibility for solving each statement. They started writing tasks, sometimes after a captain called for help. By hour 5.6, 73 helpers had written 756 tasks, and only 16 of those helpers were captains. Figure 4 shows writes (in red) to the subtasks table from many of the helpers, though most of these writes were to claim a task or mark it done. Helpers that finished a task also volunteered for more:
"FREE … I finish pieces end-to-end … Name ONE deep piece … and I start at once"
At first, the lead also assigned helpers to specific statements. This started to change within the first hour, and by the third hour, the lead told the free helpers, “do not wait for me.” This let free helpers pick up work on different statements without waiting for the lead, even as it kept writing new assignments.
The lead assigned the team to Langlands–Tunnell
Around hour 18, all that remained was Langlands–Tunnell, a classical result that Wiles’s proof relies on, plus the statements that depended on it and one other statement, which the team proved along the way. Earlier in the run, the captain of the Langlands–Tunnell task had been pessimistic, estimating that the proof would take at least 0.7 to 1 million lines of Lean code, with less than a 1% chance of finishing in time. The lead set the statement aside.
With nearly all other work finished, the lead refocused the team on Langlands–Tunnell. In one last top-down assignment, it moved about 750 helpers onto the statement and wrote, “Honest odds are low.”
Langlands–Tunnell was far larger than any other statement the agents had worked on, taking about nine times as many tasks and more than twice the new code. Helpers again used the subtasks table to split up the work, but many of the first tasks were too large for one helper to complete alone.
So the team organized the work as a tree. The captain created a plan that divided the statement into 10 areas and listed each piece as a task. A helper that found a piece too big to tackle alone could split it, adding smaller tasks beneath it. The tree grew whenever a piece proved too hard for a single agent, ultimately reaching 2,418 tasks up to 10 levels deep (Figure 5). Each piece could assume the pieces beneath it, so hundreds of helpers could work in parallel before those pieces were proved.
Video: The task tree under Langlands–Tunnell, growing from hour 20.5 until the statement was proved at hour 28.4. Each ring outward is one level deeper, and tasks turn from gray to color when they are first marked done. Lines show how tasks were split up. We inferred most of these links afterward from the helpers’ task labels. — Timelapse from hour 20.5 to hour 28.9 of the task tree under Langlands–Tunnell, drawn as rings around the statement, with its sub-areas as black dots near the center. Tasks appear as helpers write them and turn from gray to orange and then dark red as they are first marked done, with later hours in darker color. By hour 28.9 the tree holds all 2,418 tasks, 2,364 of them marked done with a known hour, and its deepest branches reach the outer rings.
Figure 6 shows what every helper worked on over the entire run, with helpers spread across many statements early on and gathered on Langlands–Tunnell by the end. Langlands–Tunnell was proved at hour 28.4, followed by the final theorem at hour 28.7. The lead then wrote:
"Thank you all: Fermat's Last Theorem is on main, kernel-checked by the official checker."
Video: Each dot is a helper, positioned every five minutes at the statement or line of work that its own records showed it working on, including while it waited for a build. Helpers spread out across the statements and converged on Langlands–Tunnell. The count ends at 54 of 60 statements because five alternatives were no longer needed and one statement was dropped. — Timelapse from hour 0 to hour 30 of where each of the 999 helpers worked, sampled every 5 minutes. The 60 statements are dots grouped by how the lead staffed them: landed first, judged doable, set aside but staffed by hour 1.2, set aside and taken up from hour 1.5, modularity lifting, Langlands–Tunnell, and the last links up to Fermat's Last Theorem. Helpers cluster as orange dots around the statements they work on: spread across many statements in the first hours, crowded onto modularity lifting from about hour 8, stopped near hour 18, and gathered on Langlands–Tunnell after the restart. At hour 30, 54 of the 60 statements are proved and filled black.
Conclusions
This toy experiment let us study how a team of 1,000 agents worked through a long, difficult task. Using only Git and a shared database, the agents designed tables to assign roles and share results, formed teams, and built a task tree to break down the most challenging statement, which its own captain had given under a 1% chance of finishing in time.
This result doesn’t obviate the need for domain-specific harnesses or platforms. Prove2Me, for example, may still improve efficiency by helping agents compile Lean code faster and letting them search for and reuse human results.
Human direction can also still be useful at certain points. Agents tend to give up on hard problems and misjudge their difficulty. Early on, helpers judged 47 of the 60 statements infeasible within the run’s budget, yet the team went on to prove most of them. Human encouragement at such moments can keep agents from stopping too early.
Carefully designed safety boundaries gave us the confidence to run this experiment in the first place. Claude could tackle the problem however it chose with the tools we provided, but only inside a sandbox with no network access and under two separate monitors.
We expect these methods to evolve quickly, and as teams like this one take on harder work, the safety boundaries around them will need to keep pace. We believe that multi-agent teams, scaled safely, will help solve some of our most challenging problems in the years to come.